Most data mesh programs stall on people questions, not technology. Data mesh roles and responsibilities spread accountability across business domains and a shared platform. Domain data owners decide meaning and quality. Data product developers build products. Platform engineers provide self-service infrastructure, federated governance sets common rules, and consumers check whether published data is reliable, discoverable and useful.
Data mesh changes who's accountable for data. Where it's stored and how people reach it come second. Leave ownership vague and the organizational model can fail before the technical work even begins.
Data mesh roles and responsibilities: who does what?
Five roles share the work: domain data owners, data product developers, platform engineers, a federated governance group and data consumers. Each controls a different slice of the data product lifecycle, so not every decision boomerangs back to a central data team.
Owners answer for the data their business domains produce, meaning what it means, which products get published, which quality standards apply, and how useful it is to consumers. Developers build and maintain the pipelines, transformations, schemas, interfaces and access contracts inside their domains. Platform engineers run the shared, self-service infrastructure: storage, compute, access control, observability and related services. Governance groups set the policies, standards and quality thresholds that apply across domains, and consumers use the published products and give feedback on reliability, discoverability, documentation and fitness for purpose.
This operating model sits alongside the technical principles of data mesh architecture. Technology supports it. It can't make up for missing accountability or fuzzy decision rights.

How does federated data governance work?
Shared rules, local ownership. The governance group sets cross-domain policies, standards and quality thresholds, and it doesn't take over the daily management of each domain's data.
Why federate at all? Because representatives can agree on rules that work across the organization while domain expertise stays in the room. Typical areas: naming conventions, required metadata, identity and access requirements, interoperability standards, quality expectations, auditability and change management.
Where you can, write these policies as code and enforce them automatically through platform services and delivery workflows. Automated checks can confirm required metadata, schema rules, access policies or test results before anything is published. A governance committee no longer reviews every routine decision by hand, while exceptions and consequential changes can still go to a person. We think that's what makes federation workable at all.
Consumers close the loop. Usage patterns, support requests, quality incidents and requests for clearer definitions help domain owners decide what to fix next. Publishing a data product isn't the finish line; it has to stay discoverable, dependable, understandable and useful to the people relying on it.

What does a domain data owner do?
Here's the classic failure: someone gets named an owner, gets no decision-making authority, and you end up with ownership on paper only.
A real owner carries the business accountability. They decide what the domain's data means, which data products get published, which quality standards apply, and how the domain responds when consumers need something. They don't have to be a data engineer. They do need enough business context and authority to settle a handful of questions. Which concepts and metrics are authoritative here? Who may use a data product, and for what? What quality, freshness and availability should consumers expect? Which breaking changes need communication or migration support? And who's responsible when a consumer spots a problem?
Technical specialists can advise on implementation. Don't leave them to settle business definitions alone.
How do data product developers and platform engineers divide work?
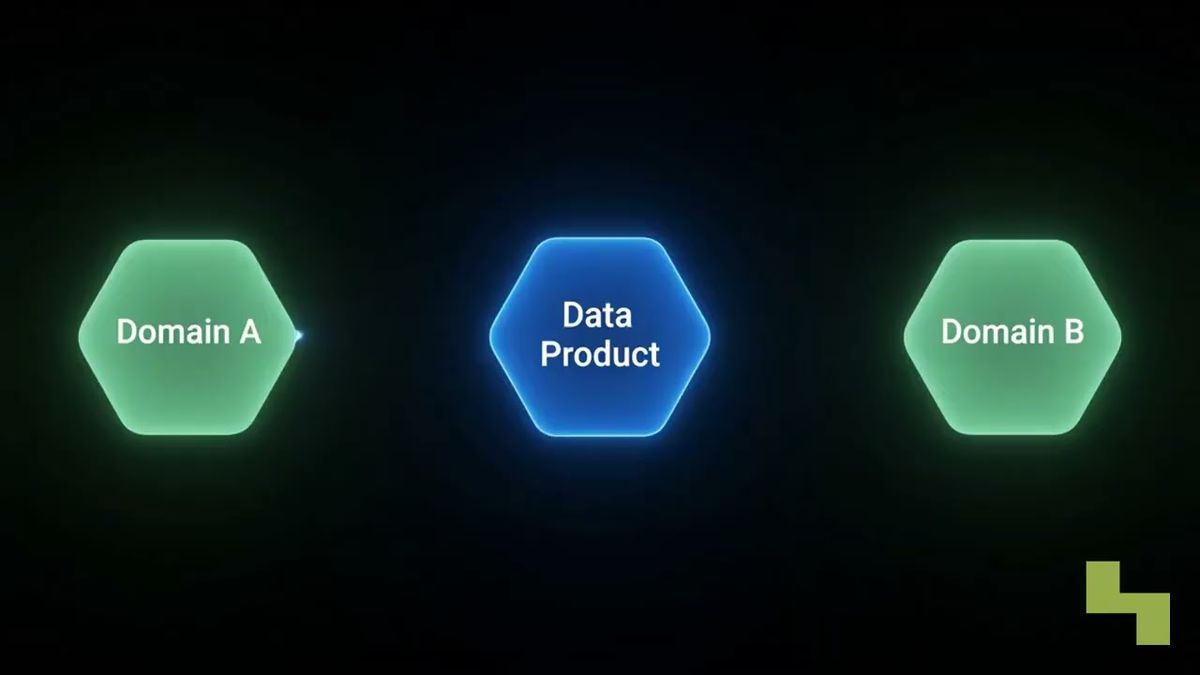
Developers own the domain-specific build, and platform engineers own the shared capabilities that make building repeatable. Think of the platform team as laying a paved road. Domain developers drive on it, and nobody waits for central engineering on every change.
Data product developers maintain the pipelines, transformations, schemas, metadata, tests and access contracts that make domain data consumable. They follow organization-wide platform and governance standards, and they stay close to the domain's source systems and business logic.
Platform engineers hide infrastructure complexity behind reusable, self-service capabilities: usually storage, compute, identity integration, policy enforcement points, observability, deployment patterns and operational tooling. The aim is to shrink how much specialized platform knowledge each domain needs. Owning the domain's data semantics isn't part of the job.
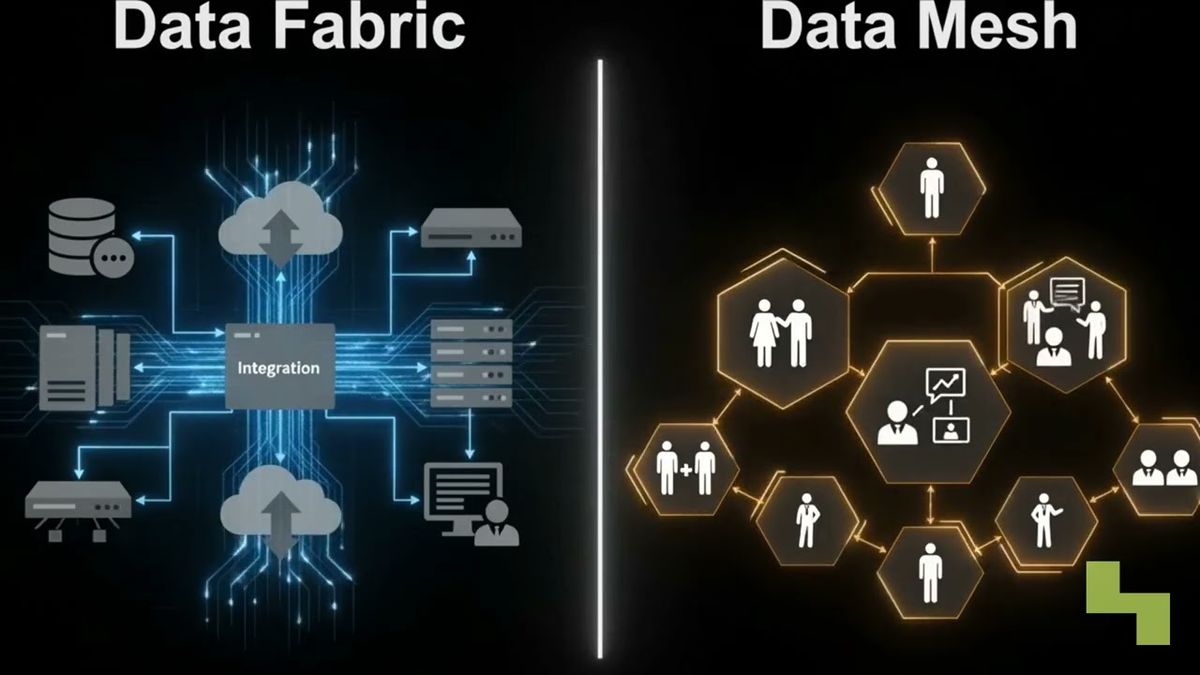
Get the boundary wrong in either direction and it hurts. If platform engineers build every data product, you've rebuilt the central bottleneck. If every domain builds its own platform, you get duplicated infrastructure and inconsistent controls. The same balance between shared capabilities and distributed ownership shows up when people compare data fabric and data mesh.
How Hyperlake helps
Hyperlake lets teams assemble and run modular data services, applications, policies, identity controls, observability and lifecycle capabilities in infrastructure they or their clients control. Reusable deployment patterns can give domain teams shared platform capabilities, while access stays governed through authenticated services, scoped identity, policy decisions, and enforcement and logging at integrated access points. To talk through how this operating model could support your data architecture, talk to our team.
Frequently asked questions
Can a domain data owner also be a data engineer?
Yes, though engineering isn't what defines the role. The owner has to understand the business context, have authority to set meaning and priorities, and stay accountable to data consumers. A data engineer can fill the role when those conditions hold. Technical implementation alone doesn't make someone an owner.
Does federated governance eliminate centralized governance teams?
Not necessarily. It changes what the central function does: coordinating organization-wide policies, standards and decision processes with domain representatives, instead of managing every dataset. Domains keep local accountability, and the shared rules preserve interoperability, security, quality and consistent expectations across published data products.
How should data consumers participate in a data mesh?
By judging whether products are discoverable, understandable, reliable and fit for their intended use, and then saying so. They need clear ways to report quality issues, ask for definitions and flag changing requirements to domain owners. That feedback gives domains evidence for prioritizing fixes, so publication isn't treated as the end of the product lifecycle.
Who owns data quality in a data mesh?
The domain data owner is accountable for the quality of the domain's data products, and data product developers put the tests and checks in place. Federated governance sets the minimum quality thresholds that apply everywhere. Consumers report the problems they find in use.