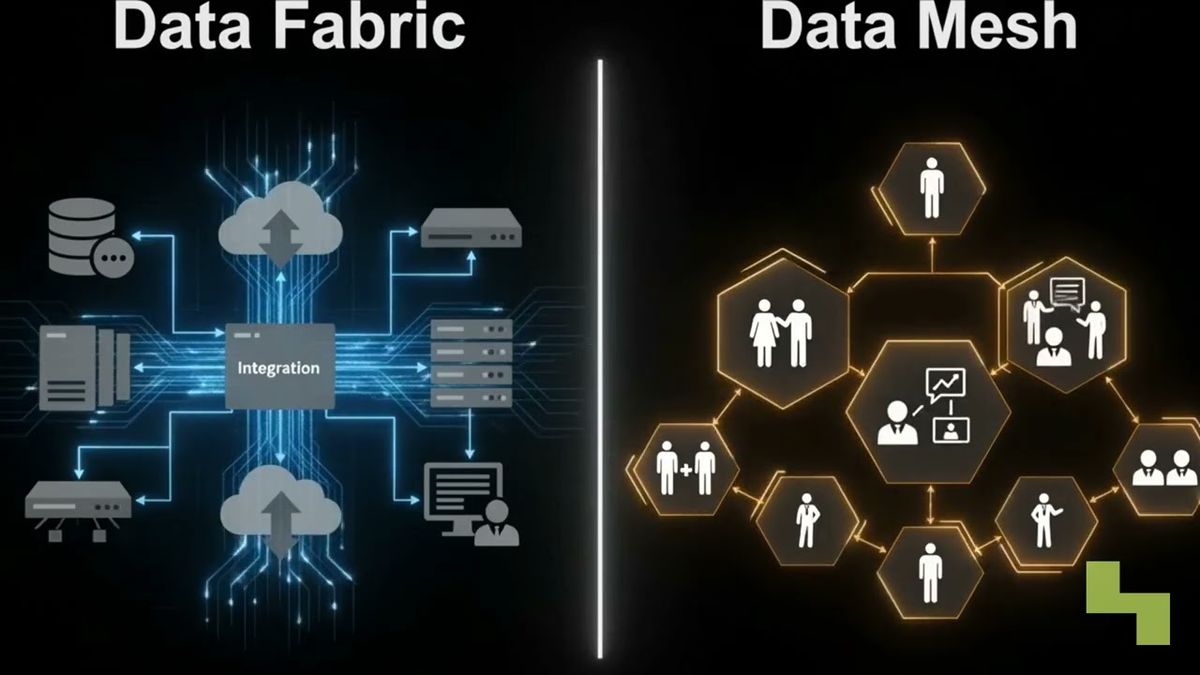
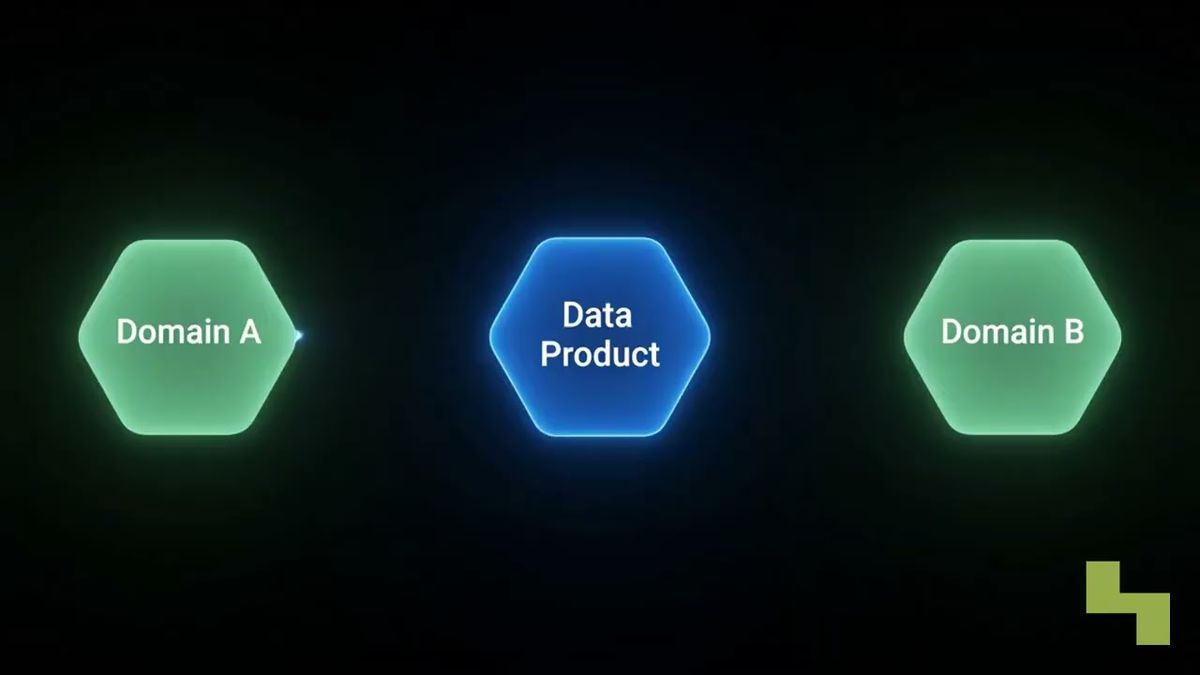
Data products vs data mesh is mostly a question of scope. A data product is a governed, reusable data asset built for consumers outside the domain that produces it. A data mesh is an organizational and architectural model that decentralizes data ownership across domains. A mesh requires data products. Data products don't require a mesh.
Get that direction right and you avoid two mistakes: over-engineering what is really a plain reliability problem, and underestimating how much organizational change decentralization takes. Our advice is to adopt product discipline for data today and think about a mesh later, once scale, domain boundaries and ownership needs actually call for one.
Data products vs data mesh: how are they related?
In one direction only. Every working data mesh depends on data products; a data product can exist without a mesh. Products are the exchange mechanism. The mesh is the decentralized structure in which domains produce and consume them.
The two get blurred, partly because data mesh brought "data product" into mainstream data engineering conversation. The need underneath is older and simpler. Before people and systems outside the producing team could use data safely, it always needed ownership, reliable interfaces, controlled access and predictable behavior.
Data mesh gave those practices a defined structural home. It didn't invent the need for reliable, reusable data.
Mislabel it either way and you pay. Call every well-managed dataset part of a mesh, and you drag in organizational implications that may not exist. Call a decentralized heap of unmanaged datasets a mesh, and you've left out the product discipline at its core.

What is a data mesh?
Think of a company where finance owns a governed revenue product and operations owns an inventory product. That's the mesh idea in miniature (a hypothetical, but the shape is right). A data mesh is an architectural and organizational model in which business domains own and publish data for use beyond their own boundaries. Domains get real autonomy, no single central data team carries all the responsibility, and data products are the main unit of exchange.
Each domain stays accountable for the meaning, quality, contract and lifecycle of what it publishes. Consumers shouldn't need to understand the producer's internal pipelines to use those products safely.
Splitting a data platform into separate accounts or teams doesn't get you there. A mesh needs clear domain boundaries, accountable owners, shared governance, and enough platform support that domains can publish and run products consistently. Without common controls, autonomy tends to produce incompatible schemas, uneven access practices and duplicated infrastructure.
So data mesh architecture is a far bigger organizational commitment than building individual data products. It changes who makes decisions, who operates data, and how domains coordinate across the enterprise.
What is a data product?
Somebody owns it, and somebody depends on it. A data product is a unit of data designed and run so that other teams, applications or automated systems can rely on it, with an accountable owner and an explicit contract with its consumers.
What it looks like on the outside matters less than the discipline behind it. It might be a table, an API, an event stream, a dataset or another governed interface. Underneath, you'd expect a named owner, a documented schema with a process for changing it, quality guarantees (or at least clearly stated quality expectations), access controls that suit the data and its consumers, and service-level expectations for availability, freshness or support.
That's more than data sitting in storage. Someone has to know who consumes it, look after its interface, announce changes and fix quality failures, and those habits are what make the output reusable beyond the team that built it.
You don't need a new org chart for any of this. A centralized data team can publish products for business units. A small company can improve one critical shared dataset without redesigning how it operates. These data product best practices pay off with or without data mesh.
When should you start with data products instead of data mesh?
Is your problem that data is unreliable, badly documented or hard to reuse? Start with data products. Look at a data mesh when several capable domains need independent ownership and the organization is ready to coordinate governance, platforms and accountability across them.
A sensible first move is small. Pick a high-value dataset whose consumers you can name, give it an owner, define the schema contract, write down the access rules and set measurable expectations for quality and service. Then run it like a product: monitor it, manage changes, collect consumer feedback and keep the documentation current.
Nothing had to be decentralized first. And you learn something useful along the way: where central ownership turns into a bottleneck, and whether domains have the skills and incentives to take responsibility on.
Before moving toward a mesh, check for:
- Stable domain boundaries, and leaders willing to own data outcomes.
- Teams that can run products through their whole lifecycle.
- Shared governance that keeps security and interoperability intact.
- Reusable platform capabilities, so each domain isn't rebuilding the same controls.
Skip that readiness and a mesh initiative can hand out responsibility faster than it hands out capability. We'd usually start with product discipline; it's the lower-risk foundation, since it improves specific outputs and leaves the wider organizational model alone.

How Hyperlake helps
Hyperlake can provide a governed data foundation for data products, using suitable operational, analytical, search, vector, graph and streaming engines. Shared controls support identity-based access, policy enforcement, audit, lineage, observability and lifecycle operations across infrastructure the organization or its clients control. To talk through how this fits a centralized product model or a domain-oriented architecture, talk to our team.
Frequently asked questions
Can a centralized data team own and publish data products?
Yes. A central team can define ownership, schema contracts, access controls, quality expectations and service levels for data used across the organization. The product model is about how data is designed and run for consumers, so where the producing team sits on the org chart doesn't enter into it. Decentralized domain ownership becomes a requirement only if you adopt data mesh.
Do schema contracts and data quality checks create a data mesh?
Not on their own. Contracts and quality checks are core traits of data products. A mesh also decentralizes ownership across business domains and makes those domains responsible for publishing and running their products. Technical controls can support that model, but they can't stand in for organizational accountability.
How can a small organization begin treating data as a product?
Pick one shared dataset with clear consumers and give it an accountable owner. Document its meaning, schema, access policy, quality expectations and how changes get communicated. Then check whether it meets those expectations, and ask the people using it what they think. You end up with a useful data product and no new domains, no duplicated platform teams and no company-wide mesh program.