Apache Iceberg snapshots are immutable records of a table's exact state, held as metadata pointers rather than full copies of the data. Each snapshot names the manifests and data files that belonged to the table at commit time. That's what makes snapshot-isolated reads, safe concurrent updates, historical queries and efficient file pruning possible.
Honestly, we think snapshots are the most underrated idea in the whole table format.
One small piece of metadata ends up carrying reliability, query speed and time travel, and none of it needs a full copy of the table for every change. A lot of what people call modern lakehouse architecture sits on top of it.
What is an Apache Iceberg snapshot?
Append, overwrite, delete, merge: each one gives you a new version of the table. An Iceberg snapshot is the metadata record of that version. It points, through a metadata hierarchy, to the exact files that make up the table after the change. Nothing's copied. The full dataset isn't touched.
Old states survive because a commit writes new files and new metadata. Existing files never get edited in place.
So treat a snapshot as one consistent version of the table. Two readers on the same snapshot see the same table, even if some other process commits new data while their query runs. It's a central feature of data lakehouse architecture.
Snapshots are light compared with full table copies. They do still need the underlying data and metadata files to stick around, though, and your retention and snapshot-expiration policies decide how far back you can query.
How does Iceberg create a snapshot?
From the bottom up. Iceberg writes new data files, describes them in manifests, groups the manifests in a manifest list, and records a snapshot pointing at that list. Committed data files that already exist don't have to change.
Simplified, a commit goes:
- Write data files. The writer creates files holding the records the operation added or rewrote.
- Create or update manifests. A manifest lists data files and records metadata about what's in them, including useful column statistics.
- Build the manifest list, which names the manifest files for this snapshot.
- Commit the snapshot. A snapshot entry goes into the table metadata state and points to the manifest list.
Read it top down and you go table metadata, then snapshot, then manifest list, then manifests, then data files. Iceberg can also reuse manifests and files that are still part of the new table state, so it skips metadata work it doesn't need.
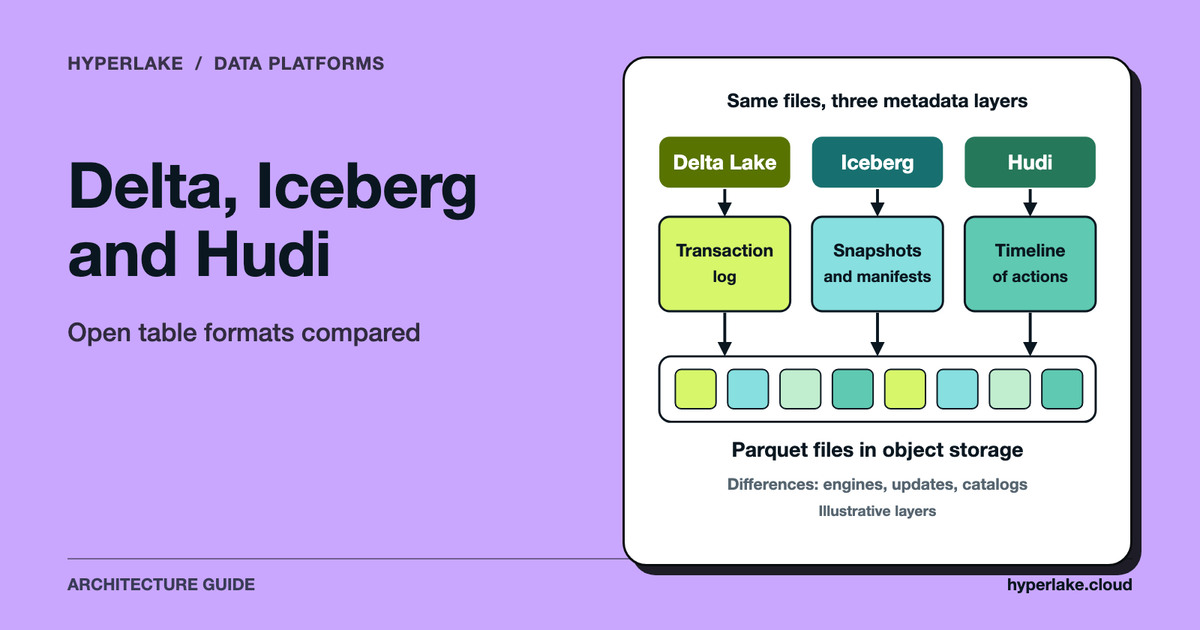
Because a commit publishes a whole new metadata state, readers can always find a consistent table through its metadata pointer. Keeping metadata apart from immutable files is also what separates Iceberg from layouts that rely on directory listings or file sets that change underneath you. For a wider format comparison, see Apache Iceberg versus Delta Lake.

How does Iceberg snapshot isolation keep concurrent reads and writes safe?
A reader stays pinned to one immutable snapshot while a writer prepares and commits another. Data landing halfway through a query doesn't change what that query sees. Not even a little.
Writers usually create their files first and only then try to publish new table metadata. At commit time Iceberg uses optimistic concurrency control. If another writer has changed the relevant table state, the conflicting operation may need validation, a retry or reconciliation; it never quietly overwrites the other writer's work.
That's snapshot isolation for reads. A long query keeps using the files from the snapshot it started on, and newer queries pick up the newly committed state. Readers and writers stay out of each other's way, because nobody edits shared files in place.
One operational catch: file cleanup has to respect snapshot retention. If a retained snapshot still references a file, you can't delete it just because the newest table state stopped using it.
How do Apache Iceberg snapshots enable time travel and file pruning?
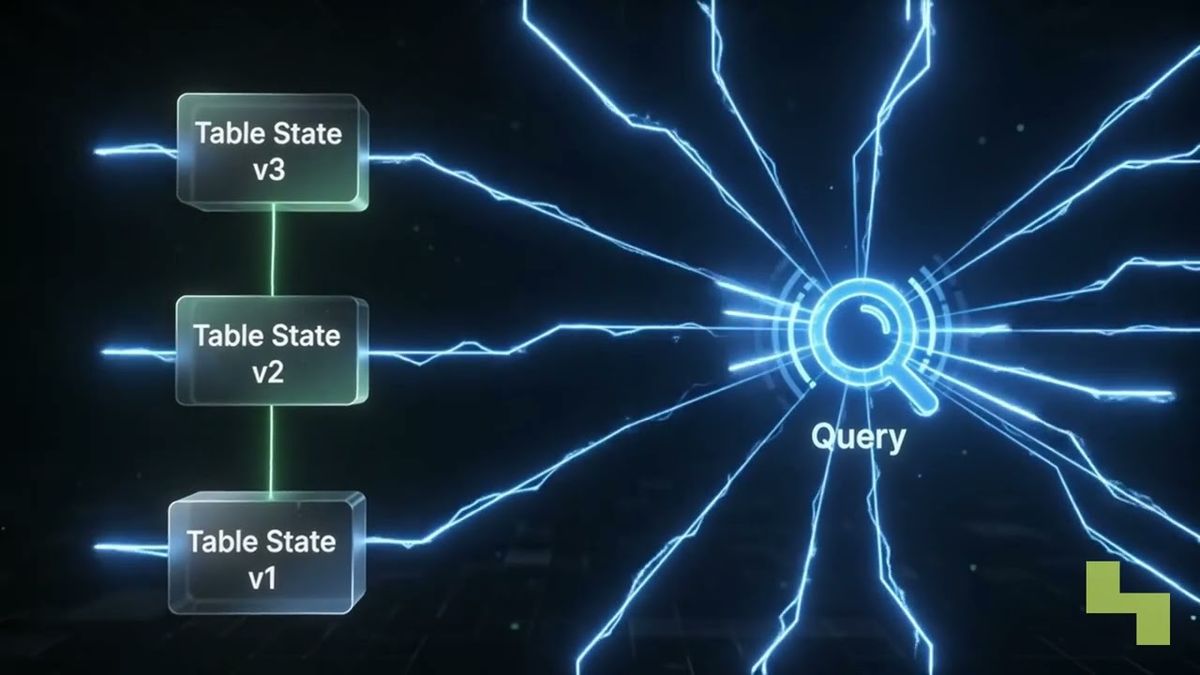
Same metadata hierarchy, two payoffs. Snapshots keep pointers to earlier valid table states, and that's time travel. Their manifests describe files before a query opens them, and that's pruning.
For time travel, a query picks a historical snapshot by identifier or timestamp (which one depends on the query engine). You aren't restoring anything. The engine reads the old state straight from the files that snapshot references. It only works while the snapshot and the files it needs are retained.
For query planning, manifest metadata can include column-level statistics, like lower and upper value bounds for each data file. When a query has a predicate, the engine compares it with those statistics and drops files whose ranges can't contain a match.
A simple case. A file's recorded range can't satisfy your date or numeric filter? The engine skips it without reading a single row. On a large, well-organized table, metadata-driven pruning can rule out many irrelevant files before any scanning starts. How well it works depends on the filters, data distribution, file layout, available statistics and query engine.

How Hyperlake helps
Hyperlake is the AI cloud for your team and your agents, on your cloud. It can assemble a governed data foundation from Iceberg and object storage with a suitable query engine, adding operational, search, vector, graph and streaming services when the workload calls for them. Teams can deploy and run that foundation in their own infrastructure or a client's environment, with shared controls for identity, access, observability, lifecycle and audit; operating procedures vary by engine and solution pack. To talk through an Iceberg-based data environment, talk to our team.
Frequently asked questions
Does every Iceberg snapshot contain a separate copy of the table?
No. A snapshot is mostly a metadata structure naming the manifests and files that belong to one table state. Several snapshots can point at some of the same immutable data files, and newer ones add or replace file references as the data changes.
Can Apache Iceberg snapshots replace data backups?
No, please don't treat them that way. Snapshots give you table history and a way back from some logical mistakes, but they rely on the underlying metadata and data files staying intact. Backups, replication, access controls and tested disaster-recovery procedures cover infrastructure loss, accidental deletion and failures beyond normal table history.
What happens when two writers update an Iceberg table at once?
Each writer prepares new files and tries to commit a new metadata state, and Iceberg checks each commit against the current table state. Compatible operations may go through. Conflicting ones can need a retry or fail validation, which stops one writer from silently replacing the other's committed work.