A lot of bad RAG answers start with a bad split. Semantic chunking vs. hierarchical and structure-aware chunking comes down to where each one draws the line. Semantic chunking cuts text at natural topic shifts. Hierarchical chunking retrieves small child passages and keeps links to broader parent context. Structure-aware chunking follows headings, tables and code blocks, avoiding the damage fixed-length splitting does in retrieval-augmented generation systems.
Embedding models can only take so much text at once. Assistants, meanwhile, need the whole piece of evidence to answer a detailed question.
Draw the boundaries badly and a definition gets cut off from its qualifier. A table is sliced in half. A passage comes back with too little around it to mean anything.
Semantic chunking vs. hierarchical and structure-aware chunking: how do they differ?
Each one decides where a chunk ends using a different signal. Semantic chunking listens to meaning. Hierarchical chunking holds several levels of context. Structure-aware chunking trusts the document's own layout. The baseline, fixed-length chunking, ignores all three.
- Fixed-length. Splits after a set number of characters or tokens. Simple, but it can chop through a coherent idea or a technical structure.
- Semantic. Spots meaningful shifts between neighboring sentences or passages and puts boundaries near them.
- Hierarchical. Small child chunks for precise retrieval, each linked to a larger parent section that supplies context.
- Structure-aware. Headings, paragraphs, lists, tables, code blocks and formatting markers become the boundaries.
They all answer the same problem: documents are often too big to embed or retrieve as one unit. A good method keeps enough meaning to retrieve well, without making chunks so broad that irrelevant text waters down the match.

How does semantic chunking find topic boundaries?
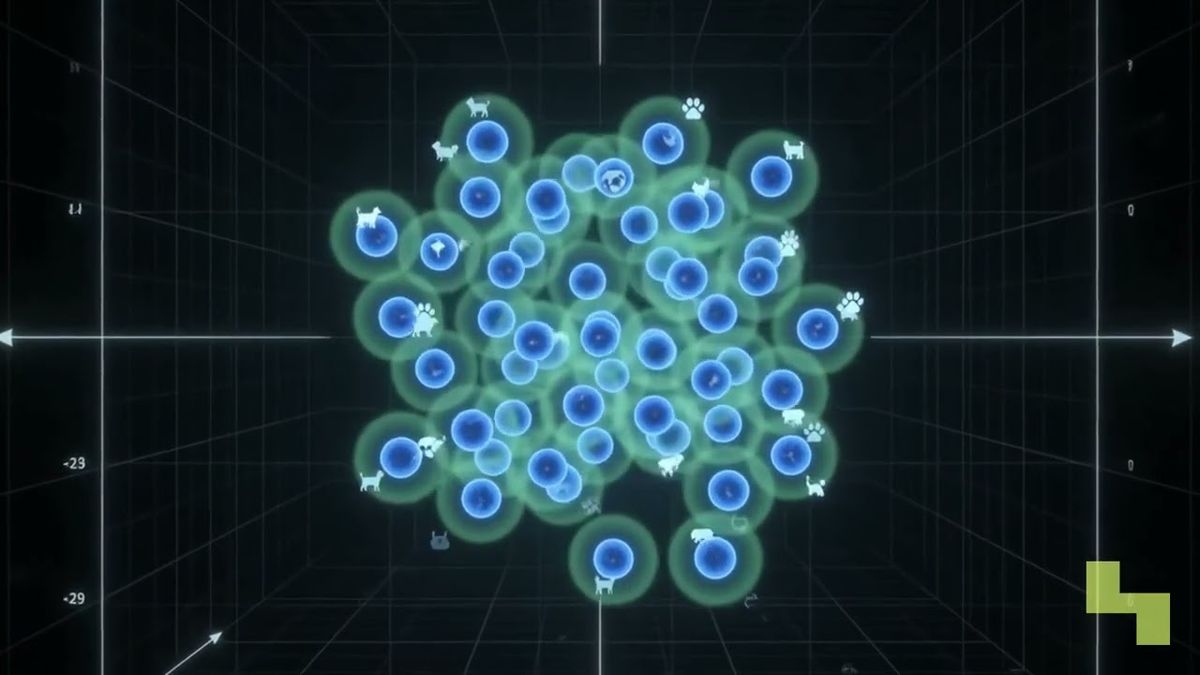
It watches for the moment the subject changes. The method compares the meaning of adjacent text units and starts a new chunk when the relationship shifts a lot. Sentences about one concept stay together, instead of being cut because a token limit happened to arrive.
Roughly:
- Break the document into sentences or small passages.
- Turn each into an embedding, or compare them some other semantic way.
- Measure how similar neighbors are and flag the big drops.
- Merge related units, staying inside the embedding model's practical limits.
The threshold is where people get burned. Too sensitive, and you end up with a pile of fragments. Too loose, and unrelated ideas share one chunk.
So test it. Run real questions, check the expected evidence comes back, and keep an eye on the context limits of the model downstream. One threshold won't suit every document collection.
Why does hierarchical chunking use parent and child chunks?
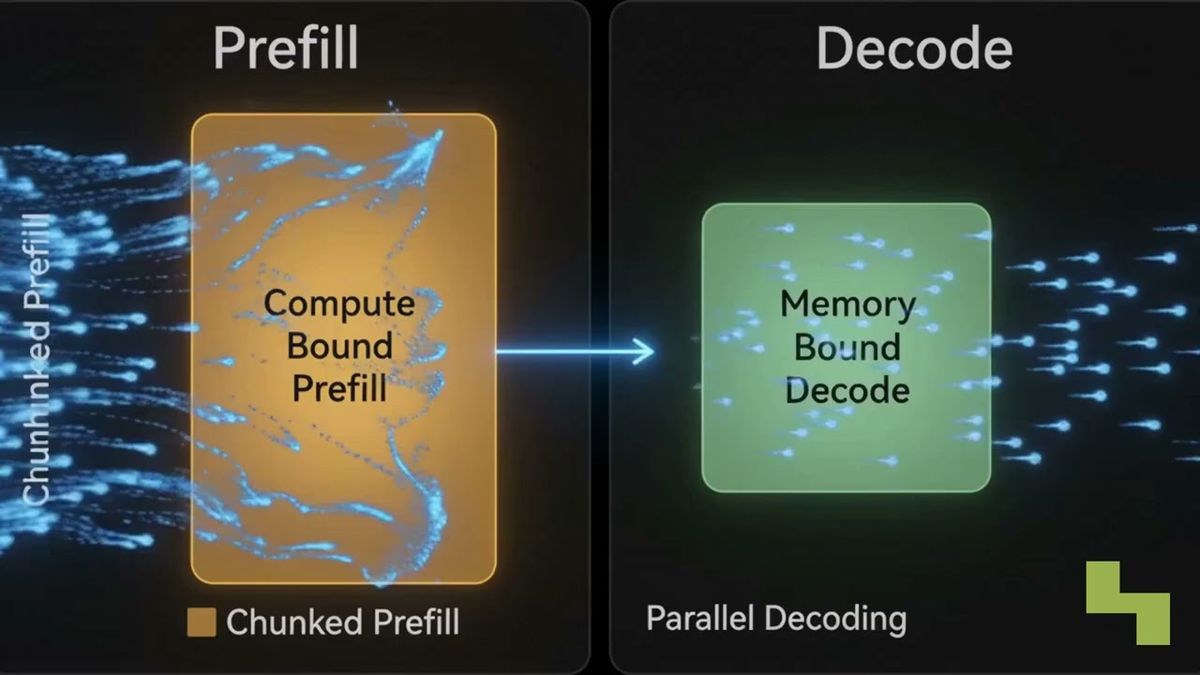
Because the best unit for finding a passage isn't the best unit for answering from it. Hierarchical chunking pulls those two jobs apart. The system searches compact child chunks, then hands the language model the linked parent section so it can make sense of the match.
Picture a technical manual. One child chunk holds a single configuration parameter. Its parent is the whole configuration section, with prerequisites, exceptions and related settings.
Retrieve only the child and the answer may come out incomplete. Embed only the parent and the exact parameter gets harder to find.
Parent-child retrieval gives you sharp matching and coherent generation together. It also pairs well with contextual compression and reranking, which can tighten the evidence after the first pass. In the hierarchical chunking vs semantic chunking debate, here's what we'd stress: they solve different problems, so you often want both.
How should you choose a chunking strategy?
Start from three things: your source documents, the questions people will ask, and how much context a right answer needs. Plenty of production retrieval pipelines mix strategies instead of picking one.
Some rules of thumb:
- Ordinary prose where meaning drifts slowly? Semantic boundaries can help.
- Small passages that lean on nearby definitions, qualifications or procedures? Return the parent.
- Tables, code, lists, headings? Keep them whole.
- Always test with representative questions, and check that returned chunks hold the complete supporting evidence.
Here's one way it plays out. A structure-aware parser first splits a manual by headings and code blocks. Semantic analysis then divides the long prose sections, and parent-child links tie each passage to its chapter.
Then evaluate chunk size, overlap, metadata, retrieval method and reranking together. Each one shapes the context the model finally sees.

How Hyperlake helps
Hyperlake lets teams assemble and operate private AI environments with governed data, model and application services in infrastructure they control. It can run vector engines such as Qdrant or Milvus and support grounding in structured data, documents, vector search, knowledge graphs or ontologies, depending on the selected deployment. To discuss a governed retrieval architecture for your environment, talk to our team.
Frequently asked questions
Is fixed-length chunking ever appropriate for RAG?
Sometimes. It can suit uniform text, early prototypes, or jobs where keeping things simple matters more than preserving structure. Token limits and overlap stop chunks from getting extreme, but boundaries can still split related ideas. Check that retrieved passages contain complete evidence before you rely on it for detailed or high-consequence answers.
Does chunk overlap solve the problems caused by poor boundaries?
Only partly. Overlap lowers the odds of losing information right at a boundary, but it knows nothing about topics or document structure. Too much of it also duplicates content in the index, and retrieval may return several near-identical passages. Think of it as a safety net, not a replacement for meaningful segmentation.
Can semantic and structure-aware chunking be combined?
Yes, and it's often the best setup. Keep headings, tables, lists and code blocks intact first, then run semantic chunking inside the long prose sections. You can also attach parent identifiers and structural metadata to each child chunk. Retrieval then gets meaningful boundaries, precise searchable units and access to broader context during generation.
Is hierarchical chunking better than semantic chunking?
Neither wins outright, because they answer different questions. Semantic chunking decides where boundaries fall based on meaning; hierarchical chunking decides how much surrounding context comes back with a match. Many teams use semantic boundaries for the child chunks and keep parent sections for generation.