Nobody should have to wait for a stranger's 500-token essay to finish before their own answer can start. Continuous batching for high-throughput AI APIs is an LLM inference scheduling method that updates the active request batch after each generation step. Finished requests leave immediately and waiting requests take their places, so nothing waits for every sequence to finish. You get less idle GPU capacity, padding work and queueing delay, and more throughput under concurrent demand.
AI APIs have to serve requests with different prompt lengths, response lengths and arrival times on finite GPU capacity. Good scheduling lets a provider process more requests without making every user wait for the longest response in the group.
What is continuous batching in LLM inference?
Continuous batching, also called in-flight batching, schedules requests at individual generation iterations instead of as one fixed group. You keep the parallel processing benefits of batching, and the membership of the active batch can change mid-generation.
Autoregressive language models generate responses token by token. After each decode step, the server spots completed requests, frees their slots and admits waiting work when capacity allows. Longer requests stay active without blocking shorter ones from finishing or new ones from starting.
The Orca research system introduced this iteration-level scheduling approach, and it's now common in major LLM serving frameworks. It suits generative inference well, since users send prompts at different times and ask for outputs of unpredictable length.
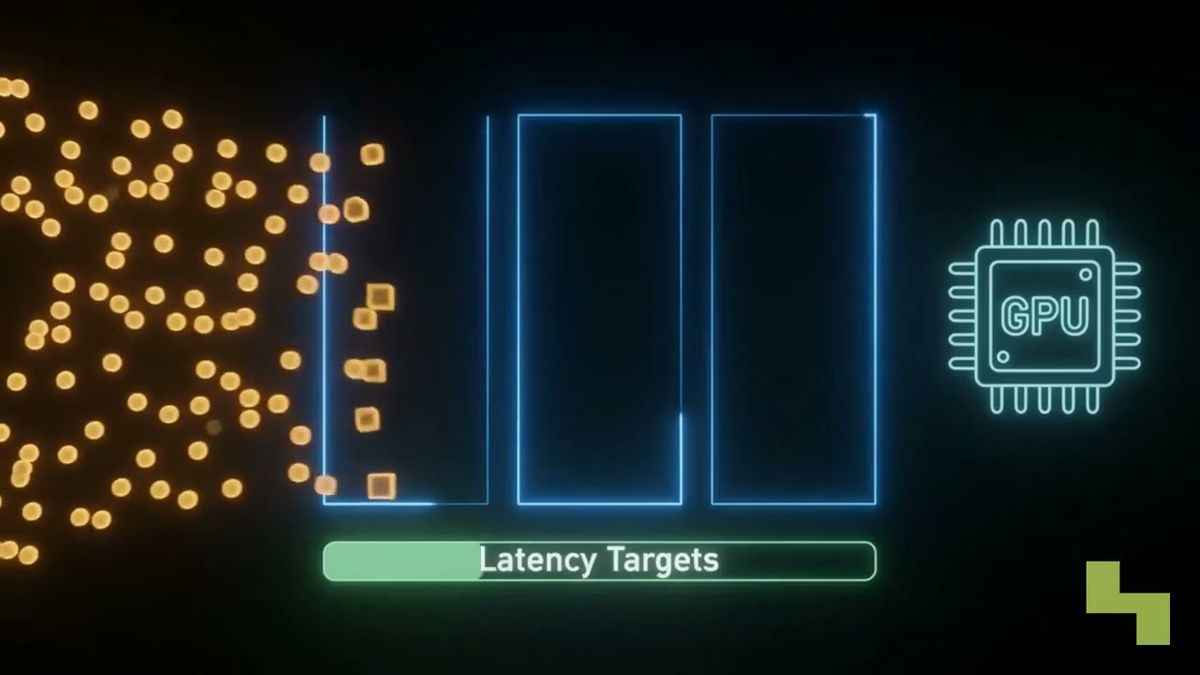
Static batching works the other way. It forms a fixed group and admits nothing new until every sequence in that group is done. If one user asks for 500 tokens and the others need 50, the short requests finish early, but their capacity sits unavailable until the long response ends.
That causes three kinds of waste:
- Tail waste, because finished requests can't release their positions while a long request keeps going.
- Padding waste, because compute may go to filling shorter sequence positions with padding tokens.
- Queueing delay, because incoming requests wait for the fixed batch to complete even when some positions are no longer doing anything useful.

How does iteration-level scheduling work?
The scheduler looks at the active batch again after every token-generation step. Waiting requests get matched with freshly available capacity right away, with no batch boundary to wait for.
A simplified scheduling loop has four stages:
- The scheduler selects requests that fit available GPU memory and execution capacity.
- The model performs one generation step for each active sequence.
- Requests that reached a stopping condition leave the batch.
- Waiting requests enter available slots, and the cycle repeats.
The server still batches compatible work to use GPU parallelism. What changes is that no request is locked into the same batch membership for its whole lifetime. Useful work keeps flowing as requests come and go.
A production scheduler also has to juggle memory limits, sequence lengths, priorities and latency objectives. Related optimizations, including chunked prefill and FlashDecoding, target bottlenecks inside prompt processing and token generation.

How does continuous batching for high-throughput AI APIs improve latency?
It keeps more GPU capacity busy with useful request work, which lifts throughput. It can also cut user-facing latency, because a new request doesn't have to wait for every sequence in some unrelated fixed group to finish.
The practical effects:
- GPU utilization goes up, since completed sequences get replaced and don't leave idle positions behind.
- Throughput rises, because the server isn't held back by the longest sequence in each fixed batch.
- Queueing latency drops, as waiting requests enter at iteration boundaries instead of full-batch boundaries.
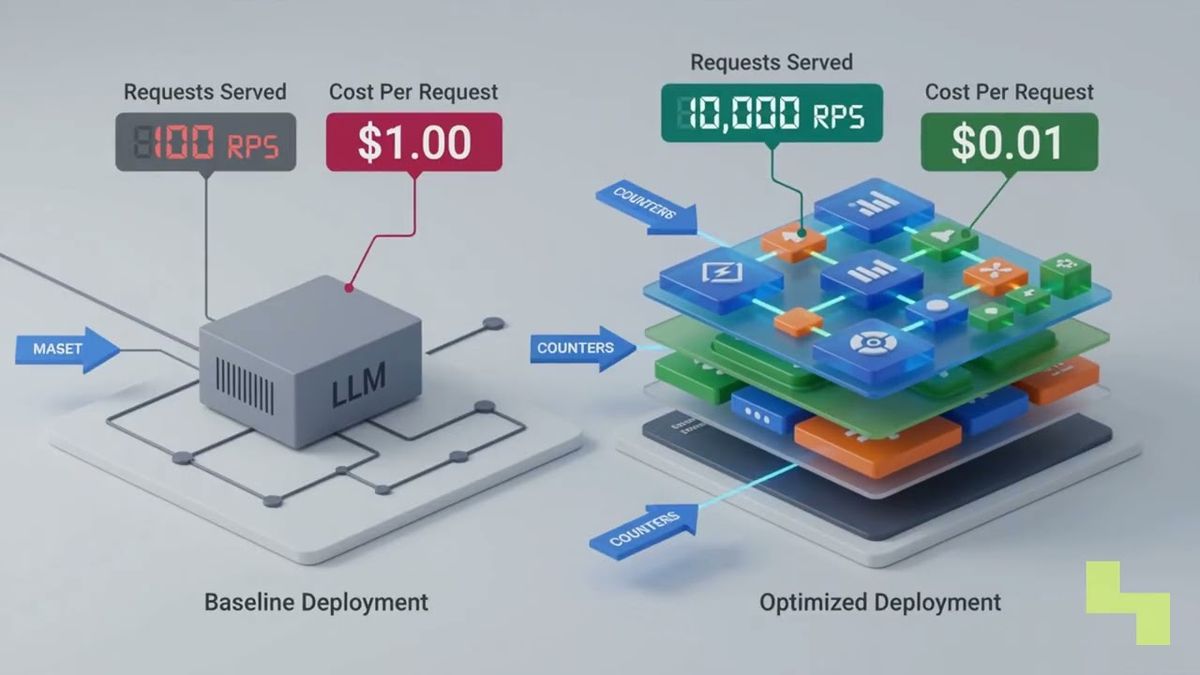
- Serving economics improve, since better utilization can lower infrastructure cost per completed request.
Actual results depend on the model, hardware, prompt distribution, output lengths, memory pressure and traffic pattern. And continuous batching can't beat physical capacity limits. If arrivals outpace what the serving pool can process, requests will queue, so you still need workload and AI cost observability next to efficient scheduling.
What causes prefill-decode interference?
A newly admitted request starts its compute-heavy prompt-processing phase while existing requests are in the middle of decoding tokens. The prefill work can hold up ongoing decode iterations, so users already receiving a response see uneven token latency.
The two phases behave differently. Prefill processes many prompt tokens in parallel and leans on compute throughput. Decode generates individual tokens over and over and is sensitive to responsive memory access and scheduling.
Prefill-decode disaggregation tackles this by putting the phases on dedicated hardware pools. Prefill workers handle incoming prompts, then pass the required model state to decode workers that carry on generating. That isolation adds architectural and operational complexity. Whether it pays off depends on workload scale, latency requirements, hardware and serving-engine capabilities; our rule of thumb is to measure the interference first before redesigning around it.
How Hyperlake helps
Hyperlake is the AI cloud for your team and your agents, on your cloud. It lets teams assemble, deploy, govern and operate private AI services in infrastructure they or their clients control. It can serve open models through KServe, subject to the deployment and validated integration, with shared controls for identity, policies, observability, lifecycle management and infrastructure usage. To discuss a model-serving architecture for your workload, talk to our team.
Frequently asked questions
Does continuous batching change an LLM's output quality?
It shouldn't by itself. Continuous batching is a serving and scheduling technique, not a model-training method: it changes when requests get GPU execution time, not the model weights or generation settings. Output differences can still come from sampling parameters, nondeterministic execution or framework implementation details.
Is continuous batching the same as ordinary request batching?
No. Ordinary static batching builds a fixed request group and waits for every member to finish before admitting another group. Continuous batching updates membership between generation iterations, so completed requests leave and waiting ones enter while longer responses keep going.
Can continuous batching eliminate AI API queues?
It can shorten them by using GPU capacity more efficiently, but it can't get rid of them when demand exceeds serving capacity. Queueing also depends on model size, prompt and response lengths, available memory, scheduling policy, hardware and latency objectives. You may still need more capacity or workload controls.