Videos · · 2:08
Tensor Parallelism vs Pipeline Parallelism vs Sequence Parallelism
Tensor parallelism, pipeline parallelism, and sequence parallelism split model work across GPUs to improve scale, memory capacity, and utilization.
Tensor parallelism, pipeline parallelism, and sequence parallelism split model work across GPUs to improve scale, memory capacity, and utilization.
 2:46
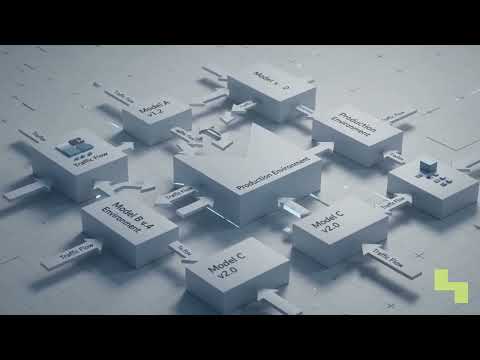
AI model deployment is the continuous process of serving, updating, evaluating, scaling, monitoring, and governing production models over time.
Watch the video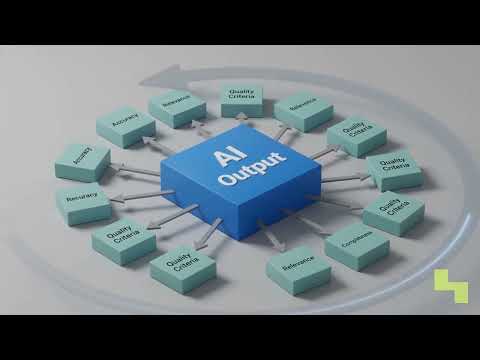 2:52
AI observability combines logs, metrics, traces, and evaluation to reveal whether probabilistic systems are reliable, appropriate, compliant, and useful.
Watch the video 2:31
AI platform engineering gives teams shared model access, observability, evaluation, cost controls, and governance for secure, scalable AI delivery.
Watch the videoExplore example deployments, or see how the platform assembles, deploys, governs and operates the stack.