Data lake vs. data warehouse vs. data lakehouse is really a question of when you apply structure. A data warehouse stores curated, structured data for reliable SQL reporting. A data lake stores raw data of many types for flexible processing. A data lakehouse keeps lake-style object storage and adds warehouse-style schema enforcement, transactions and versioning. Which one you need depends on your data shape, governance, workloads and operating model.
Analytics and AI want flexible access and trustworthy data, both at once. Pick the wrong pattern and you get rigid pipelines, duplicated platforms, or a badly governed data swamp that nobody can safely use.
Data lake vs. data warehouse vs. data lakehouse: what's the difference?
Timing.
Warehouses provide managed analytical tables and query services; many can load raw or semi-structured data before transformation. Lakes retain diverse data for later processing, while lakehouses add a managed table layer to lake-style storage. Compare the actual formats, controls and engines each system supports.
The warehouse is the oldest of the three, and each one answers a different set of needs:
- Data warehouse. Curated tables support SQL reporting and analysis. Modern warehouse services can also accept raw or semi-structured inputs and transform them after loading; supported data types and governance depend on the service.
- Data lake. Data stays raw or lightly processed, and structure is applied on read (schema-on-read). That handles structured tables alongside documents, logs, images, sensor data and clickstreams.
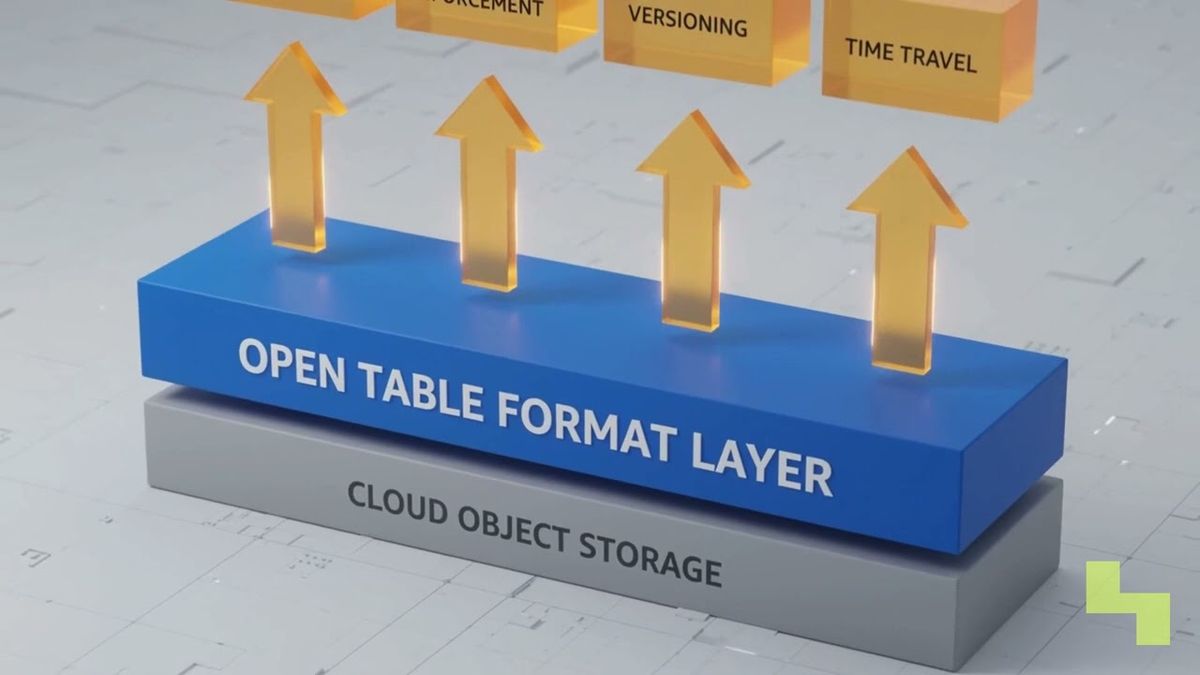
- Data lakehouse. Data stays in open file formats on object storage, and an open table format adds schema enforcement, transaction management and versioning. The lake's flexibility, with warehouse-style reliability.

When should you use a data warehouse or a data lake?
Pick a warehouse when consistent business reporting comes first. Pick a lake when diverse data and flexible processing matter more. Neither wins across every workload.
Warehouses suit dashboards, financial reporting and repeatable SQL analysis over carefully modeled data. Schema-on-write buys consistency. The costs: schema changes can be rigid, scaling can get expensive, and unstructured data such as documents or images doesn't fit naturally.
Lakes grew up to deal with those limits. Cheap object storage can hold large amounts of raw sensor data, text, images, clickstreams, logs and tables, without every use case defined up front. Great for data science and machine learning. It also pushes more of the burden onto governance and metadata management.
And here's the trap. Without schema controls, transaction management, ownership and quality processes, a lake fills with conflicting or untrusted datasets. People call that failure state a data swamp. Storage alone won't get you out of it. You need a deliberate AI data strategy.
Why are data teams adopting the lakehouse architecture?
They want to run BI and machine learning on one governed storage foundation. A lakehouse can cut the duplication and processing delay that come with separate lakes and warehouses.
It uses object storage and open file formats for flexible, economical retention. On top, an open table format adds what you'd expect from an analytical database: enforced schemas, atomic transactions, consistent updates and table versioning.
Raw data and governed analytical tables can then live side by side. Machine learning workloads get broad, detailed datasets. BI tools query curated tables with stronger consistency. That table layer is what makes a lakehouse more than a pile of files in object storage.
So many data teams are settling on the lakehouse as their primary analytical platform, and they've stopped shuttling data between a lake and a warehouse. The table technology you choose still matters. Our comparison of Apache Iceberg and Delta Lake looks at how two common formats handle lakehouse management.
How do you choose the right data architecture?
Look at data types, query patterns, governance requirements, consumers and operating constraints. The label on the architecture tells you very little. We think a lakehouse is often a strong default for mixed analytics and AI, though focused reporting systems may still be better off with a warehouse.
Work through it in this order:
- Identify the data. Is the platform mostly curated tables, or does it also have to keep logs, documents, images, events and sensor streams?
- Define the consumers. Dashboard users, SQL analysts, data engineers, machine learning pipelines and AI applications each need something different, so separate them.
- Set correctness requirements. Decide where schemas, transactions, versioning, lineage, access controls and quality checks have to be enforced.
- Model operations and cost. Count storage, query compute, data movement, duplicated pipelines, platform maintenance and the skills you'll need to run it.
The short version of data lake vs. data warehouse vs. data lakehouse? A warehouse still makes sense for narrow, stable reporting workloads. A lake works for flexible retention if your organization can supply the governance it lacks. A lakehouse gets compelling when you need governed analytical tables and broad data access without running separate primary platforms.

How Hyperlake helps
Hyperlake can assemble a governed data foundation from Iceberg and object storage with a fitting query engine, plus operational, search, vector, graph and streaming services where the workload needs them. Shared controls can tie identity, policy, audit, lineage, observability and lifecycle operations together across deployments in your infrastructure or a client's environment. To talk through the architecture and deployment constraints for a specific workload, talk to our team.
Frequently asked questions
Can a data lakehouse completely replace a data warehouse for BI?
For many BI workloads, yes. It provides governed tables, transactional consistency and SQL access over object storage. Whether it fully replaces a warehouse depends on query performance, concurrency, existing integrations, operational maturity and reporting requirements. A specialized warehouse may still be the right call for stable or highly focused BI workloads.
Why does a data lake become a data swamp?
Files pile up without reliable metadata, schemas, ownership, quality checks, access policies or lifecycle management. Users can't find the authoritative datasets, and they can't trust what their queries return. Object storage gives you flexible retention. It doesn't bring governance along with it.
Is object storage with Parquet files automatically a lakehouse?
No. Files in object storage give you a lake-style storage layer. A lakehouse also needs table management: schema enforcement, atomic transactions, consistent updates and version history. Those controls usually come from an open table format and compatible query or processing engines.