The dbt Semantic Layer is where business metrics get defined once, in code, for everyone. MetricFlow is the engine underneath: it models entities, measures, dimensions, relationships and time rules, then turns each metric request into SQL. Dashboards, analytical apps, natural-language interfaces and agents all share the same governed logic, so "revenue" means one thing.
Two departments, one meeting, two revenue numbers. Sound familiar?
That's the reason a dbt metrics layer exists. Let every team write its own calculation and the calculations wander off. You want a single controlled spot where the data team reviews, tests, audits and changes the logic that matters.
Why should dbt metric definitions be managed as code?
So a person looks at a change before your CFO ever sees it.
Keep metric definitions in version-controlled repositories, with tests, and the logic is something people can review and audit. Nobody sneaks a new formula into one dashboard on a Friday afternoon.
The controls are down-to-earth:
- Version history, so you know what changed and when.
- Peer review by data and business owners.
- Tests that flag broken references or strange results before release.
- Coordinated deploys, so no consumer sees half an update.
Roles get clearer too. The data team makes sure the technical side is correct, and business stakeholders confirm the definition says what the organization means. When a metric changes, it changes in one place, and nobody hunts through every report and app.
Does that mean tossing every calculation into one giant catalog? Please don't. Our rule of thumb: if a metric has no named owner, it isn't ready for the shared layer. You still need naming conventions, documented ownership, clear entity relationships and a policy for proposing and retiring metrics.
What problem does the dbt Semantic Layer solve?
Metric drift, the thing from the meeting above. A business calculation slowly comes apart because each team rebuilds it in its own SQL, dashboards and apps.
Picture finance and sales, both reporting monthly revenue. One uses a different date field. The other filters differently, aggregates differently, or treats adjustments its own way. Each dashboard checks out alone; side by side they disagree, and somebody burns an afternoon working out why.
The dbt Semantic Layer takes away the private copies, so every consumer reads the same shared definition. Ownership moves too: the business concept turns into a governed data asset and stops being a formula hiding in someone's report. In practice that means the same dbt metrics in every dashboard, report and app, a review step before logic changes, approved dimensions, measures and relationships that get reused, and a quick answer to "how was this number calculated?"
Storing the names of calculations isn't the point. Shipping the same executable meaning to every system is. We go wider on this in semantic layer architecture.

How does dbt MetricFlow generate SQL from metric requests?
MetricFlow is the semantic query engine behind the dbt Semantic Layer. You ask for a metric by name; it reads the central definitions (entities, measures, dimensions, relationships, time rules) and writes the SQL so you don't have to.
Say someone wants monthly revenue. A user, dashboard, app or agent requests the metric, along with the dimensions and time range it wants. MetricFlow finds the approved definition and works out which measures, entities and relationships are involved. Then it plans the joins, filters, grouping and aggregation, generates the SQL, runs it on the right analytical data system, and hands the answer back.
Look at who does what. The consumer names a business concept and never touches the math. MetricFlow covers the jump from intent to query, using definitions the data team looks after.
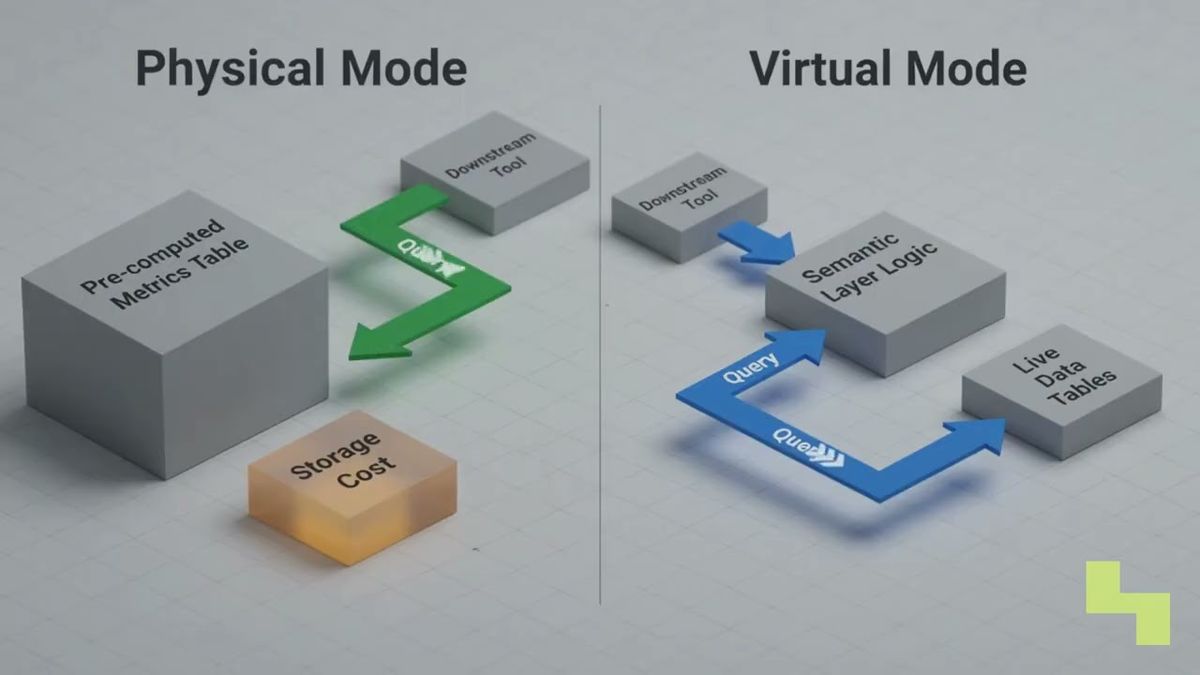
One caveat, and it's a big one: bad source data stays bad. You still need well-modeled, trustworthy tables. What the semantic layer adds is one consistent interface on top, so no downstream tool has to learn every table, join path and calculation rule alone.

How can AI agents use the dbt Semantic Layer safely?
By not letting the model guess.
Give a language model raw schemas, ask it to write SQL or invent calculation rules, and you'll eventually get a wrong number delivered with total confidence. A semantic layer offers AI agents and natural-language interfaces a trusted vocabulary for business metrics instead, and the app sends their requests through approved definitions.
So when an agent is asked about monthly revenue, it requests the governed metric with the dimensions and period it needs, and MetricFlow writes the SQL from the established logic. That leaves fewer chances for the agent to choose the wrong table, join or aggregation.
It's only half the job, though. Production systems still have to authenticate whoever (or whatever) is asking and authorize access to the underlying data. Add row or column restrictions where they're required, and log what happens. An agent should see only the metrics and dimensions its identity and task allow.
Set up that way, the semantic layer is a useful bridge between governed data and automated decisions. It pairs well with building data products for AI agents, which come with defined meaning, ownership, quality expectations and access controls.
How Hyperlake helps
Hyperlake is the AI cloud for your team and your agents, on your cloud. It can supply the governed data foundation around a reviewed semantic layer: suitable analytical engines, identity-aware access, policy enforcement, observability and lifecycle controls, in infrastructure the organization or its client controls. Its modular approach lets teams package data services, models, applications, policies and monitoring into repeatable deployments. Operating procedures depend on the chosen engines and solution. To work through an architecture for governed metrics and AI applications, talk to our team.
Frequently asked questions
Does a semantic layer replace dashboards or business intelligence tools?
No. It feeds consistent definitions and query logic to the dashboards, reports and apps you already run. Your business intelligence tools keep doing the charts, exploration and user-facing analysis, and they pull centrally governed metrics, so there's no separate calculation hiding in every workbook.
Can MetricFlow prevent every disagreement about a business metric?
No. MetricFlow makes everyone use the same implemented definition, but it can't settle a fuzzy business decision. People still have to agree on what counts as recognized revenue, an active customer or a reporting period. After they do, the semantic layer makes the agreement explicit, executable, versioned and reusable.
What must be governed beyond the metric definition itself?
Quite a lot: source data, model relationships, access permissions, the deployment process and changes in business meaning. You also need to authenticate people and workloads, enforce the data restrictions that apply, and keep logs or lineage for review. A flawless formula won't help if an unauthorized agent can query sensitive dimensions.
Can the dbt Semantic Layer and MetricFlow support LLM natural-language analytics?
Yes. The semantic layer gives natural-language apps a controlled vocabulary tied to established analytical logic. The language model identifies the metric and dimensions being asked for, and the semantic query engine generates the SQL from governed definitions. Accuracy still depends on reading intent well, on source data quality, on access controls and on sensible checks of the result.