KV cache routing sends an inference request to the server most likely to already hold reusable key-value tensors for its prompt prefix. Keeping cache locality across replicas means long, shared contexts don't get their prefill computed over and over. When no useful cached prefix exists, the router falls back to ordinary load-based placement.
Turning on prefix caching per server doesn't carry its benefit across a distributed inference cluster. That surprises people. Routing strategy alone can change the effective cost of two otherwise identical deployments.
What is KV cache routing?
Think of it as prefix caching with a map. KV cache routing is a cluster-level technique that places requests based on what each inference replica has in its cache. The routing layer learns where reusable prompt state probably lives, and that stretches prefix caching past a single server.
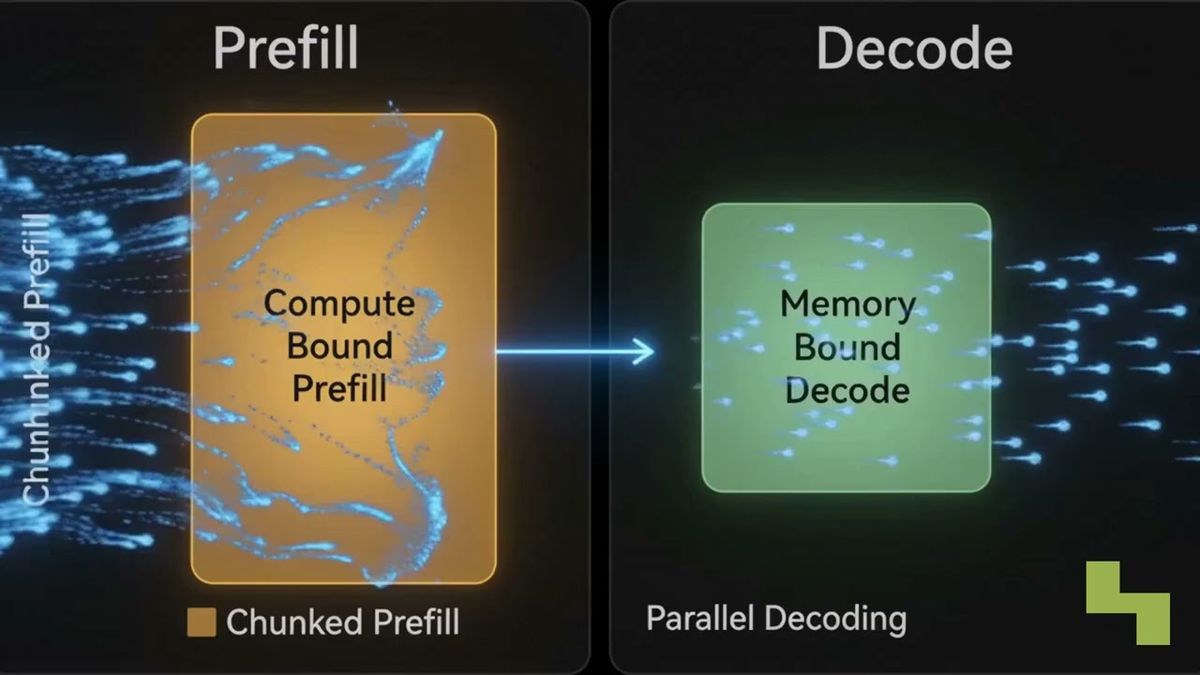
Some background. During transformer inference, the prefill phase processes input tokens and computes attention key and value tensors. If later requests start with the same tokens, a server can reuse those tensors instead of computing the shared prefix again. The longer the prefix and the more often it's reused, the bigger the potential savings.
Here's the catch. Each inference replica normally keeps its own GPU-resident KV cache. A prefix cached on one server does nothing for the next matching request if it lands on a server that's never seen it. KV cache routing fixes that through request placement. It doesn't build one shared cache across every GPU in the GPU cluster.
How does cache-aware routing work across replicas?
The router looks at an incoming request's prefix and works out which server most likely still holds reusable state for it. It prefers that server when it can, and falls back to load-based placement when there's no useful cache state.
A typical sequence:
- Identify the prefix. Derive a stable representation, often a hash, from the reusable part of the request.
- Check likely placement. Consult cache-state information that ties prefixes to inference replicas.
- Prefer a probable hit. Route the request to a replica that has likely kept the relevant KV tensors.
- Apply a fallback. If no useful state exists, look at queue depth, request count, capacity or another load signal.
Production routing has to balance locality against congestion. Send every related request to one replica and you build a queue while other replicas sit idle, so cache affinity needs to account for current load. It also complements techniques like continuous batching, which schedules concurrent work once requests reach a server.

Why does ordinary load balancing reduce cache hits?
A regular load balancer watches server load and ignores cached prefixes. Spreading matching prompts across replicas makes several servers do the same prefill computation, and the locality prefix caching depends on gets diluted.
Picture a cluster receiving lots of requests with the same long system prompt. A cache-blind policy may send consecutive requests to different replicas because each one looks a little less busy. Every server it picks then computes and stores that shared prefix on its own.
A cache-aware router concentrates similar requests on servers that have already done the prefill work, and uses load-based routing when no useful cache exists or the preferred server isn't suitable. That's how deployments with the same model, inference framework and GPU capacity end up with different effective costs: one of them repeats more prefill work. We'd count serving architecture as part of the economics of large language models, right next to model choice.

Which workloads benefit from KV cache routing?
The ones that keep sending long, stable prefixes. If requests have no reusable prefix, cache-aware routing has little prefill work to save. Different full prompts can still reuse a shared system prompt or document prefix.
Good candidates include workloads with:
- Long system prompts shared across requests.
- Repeated document contexts used for several questions or processing steps.
- Common tool descriptions included in agent requests.
- Stable instruction blocks shared across users, sessions or jobs.
Prefix-cache hit rate belongs to the workload, not the cluster. One service may mix highly reusable agent prompts, changing documents and unique user requests, and an aggregate number can hide important differences between them.
So measure hit rate by workload type, along with shared-prefix length, reuse frequency and request distribution across replicas. Then weigh the prefill work you'd avoid against the operational effort of maintaining cache-state-aware routing. That tells you whether the optimization pays off for a particular deployment. Don't assume it's useful everywhere.
How Hyperlake helps
Hyperlake lets teams assemble, deploy, govern and operate model services and supporting applications on Kubernetes-based infrastructure they or their clients control. Its modular architecture can run open models through KServe, subject to the deployment and validated integration, while shared controls support observability and lifecycle operations. To discuss cache-aware routing within a sovereign inference environment, talk to our team.
Frequently asked questions
Does KV cache routing share GPU memory between inference servers?
It doesn't. Each inference server generally keeps its own GPU-resident KV cache, and another replica can't automatically use that state. KV cache routing improves reuse by sending a matching request to the replica most likely to have already processed and kept the required prefix.
Can KV cache routing help when every prompt is unique?
Very little. A unique full prompt can still share a reusable prefix with earlier requests. When no replica retains a compatible prefix, load, queue depth and available capacity become the useful placement signals, because the uncached prefill still needs computing.
What should teams measure before adopting cache-aware routing?
Prefix-cache hit rate by workload type, shared-prefix length, reuse frequency, prefill work and request distribution across replicas. Those numbers show whether repeated system prompts, document contexts or tool definitions create useful locality. A cluster-wide average can hide big differences among workloads.
How is prefix caching different from response caching?
Prefix caching stores intermediate attention key-value tensors so the model can skip repeated prefill computation while still generating a new response. Response caching stores and returns a finished output for a matching request. KV cache routing is about where active inference work runs, not about retrieving a finished answer.