The price per token is the least interesting number on your AI bill. The economics of large language models is the total cost of producing a useful, governed AI outcome, not just the price of a model call. It combines input and output token usage with serving capacity, retrieval, orchestration, evaluation, security, audit and maintenance. Viability comes down to cost per completed task and the value that task creates.
The model with the top benchmark score may not support a viable product once usage, operations and governance are counted.
What drives the economics of large language models?
Capability and token consumption come first. Then comes the number to watch: cost per completed business task.
Why that one? A low per-token price can still add up to an expensive workflow if the system stuffs big contexts, writes long answers or makes lots of calls.
API providers usually price input and output tokens separately. Input tokens cover prompts, retrieved documents, conversation history, tool results and any instructions placed in the context window; output tokens are the text or structured data the model generates.
Pick a unit and track it: cost per conversation, per resolved request, per document processed, per agent task or per application transaction. Each one ties infrastructure consumption to an outcome, and each makes it fairer to compare models that differ in price, quality, latency and how many attempts a task takes.
Where does durable economic value in AI products come from?
Less and less from which model you picked.
For some tasks model capabilities are converging and per-token prices are falling, so access to one particular model is a weaker edge. Lasting value comes more from how well an organization combines models with domain knowledge, workflows, operational controls and reliable delivery. Retrieval design, reviewed enterprise context, fine-tuning, evaluations, tool integration and orchestration are where you can stand apart.
Governance adds economic value too. It controls who or what can reach data, records consequential actions, and lowers the operational risk of putting AI into real processes.
Choosing a model, then, stops being a one-time strategic bet and becomes an ongoing engineering decision. Pick models by task quality, latency, deployment constraints and total cost, and keep the data and application architecture around them stable. The model still matters; the whole compound system decides whether the product is dependable and economically sustainable.
What costs sit outside the LLM inference bill?
Plenty. Prototypes hide them well, since early usage is light and operational controls are incomplete. The total cost of an AI system covers compute, storage, retrieval, orchestration, governance and maintenance on top of API tokens.
Start with self-hosting. Models you run yourself bring GPU procurement or cloud GPU rental, model-weight storage, serving frameworks, capacity planning, monitoring, upgrades and ongoing maintenance. Retrieval-augmented generation adds document processing, embeddings, vector storage and query workloads that grow with the knowledge base and request volume.
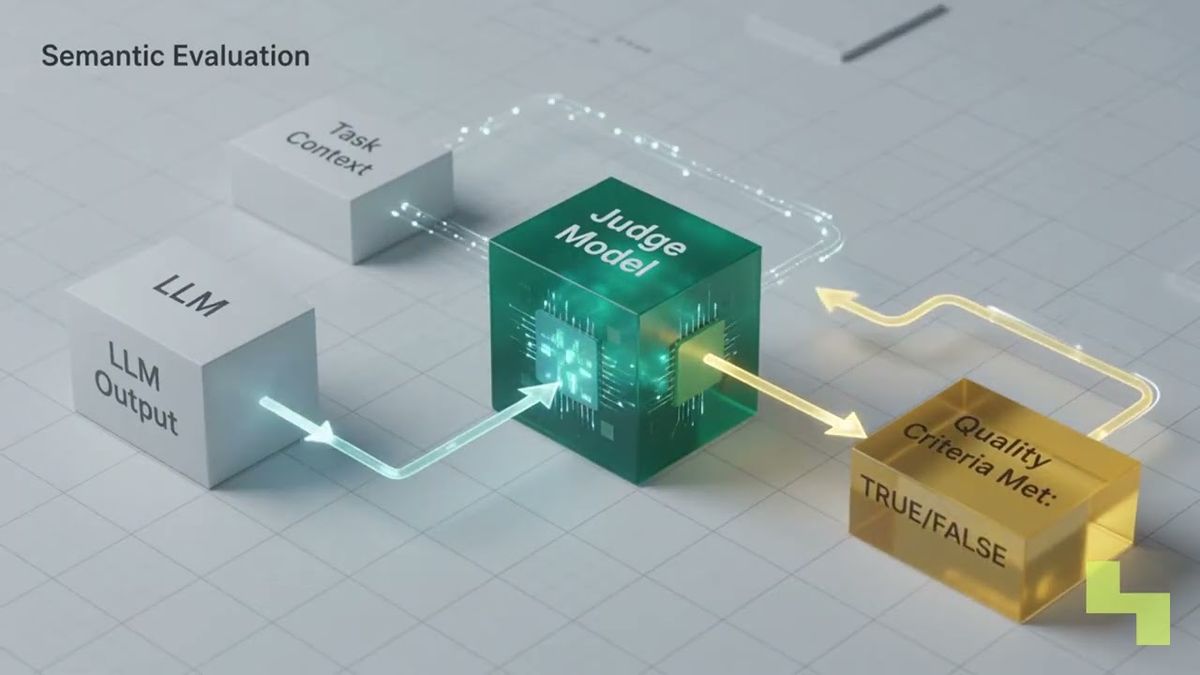
Orchestration costs compute and adds latency whenever a task takes multiple model calls, queues, state transitions or coordination steps. Governance means gateways, evaluation pipelines, audit logs, identity controls, policy enforcement and evidence retention. None of that necessarily appears on an inference invoice. All of it belongs in the total cost of ownership for your AI infrastructure.
Hosted APIs fold some operational work into per-use pricing, and self-hosting moves more of it onto your team. Owned capacity can look good for sustained, predictable workloads, but idle GPUs and maintenance can sink the case. Weigh build versus buy for AI infrastructure per workload, and use AI cost observability to connect usage with applications, agents and outcomes.

Why do output tokens cost more than input tokens?
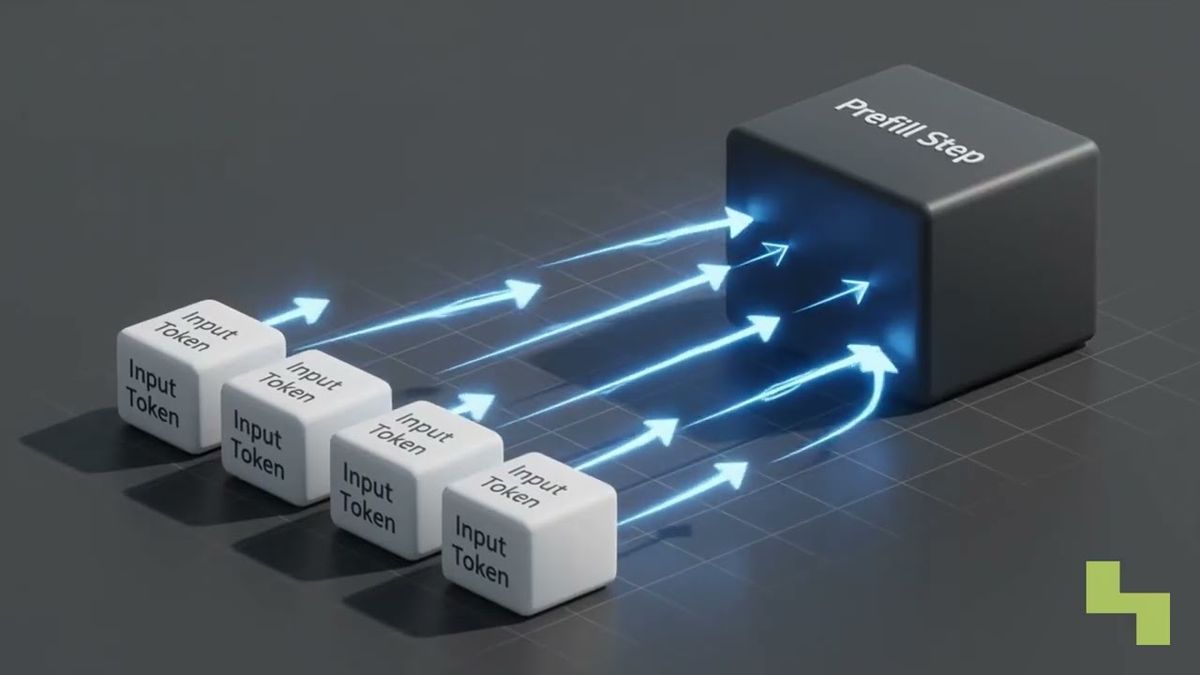
Blame the way generation works: one step at a time. Models process input tokens in a parallel prefill phase, but they produce output sequentially during decoding, and every extra generated token needs another forward pass through the model. Response length hits cost and latency directly.
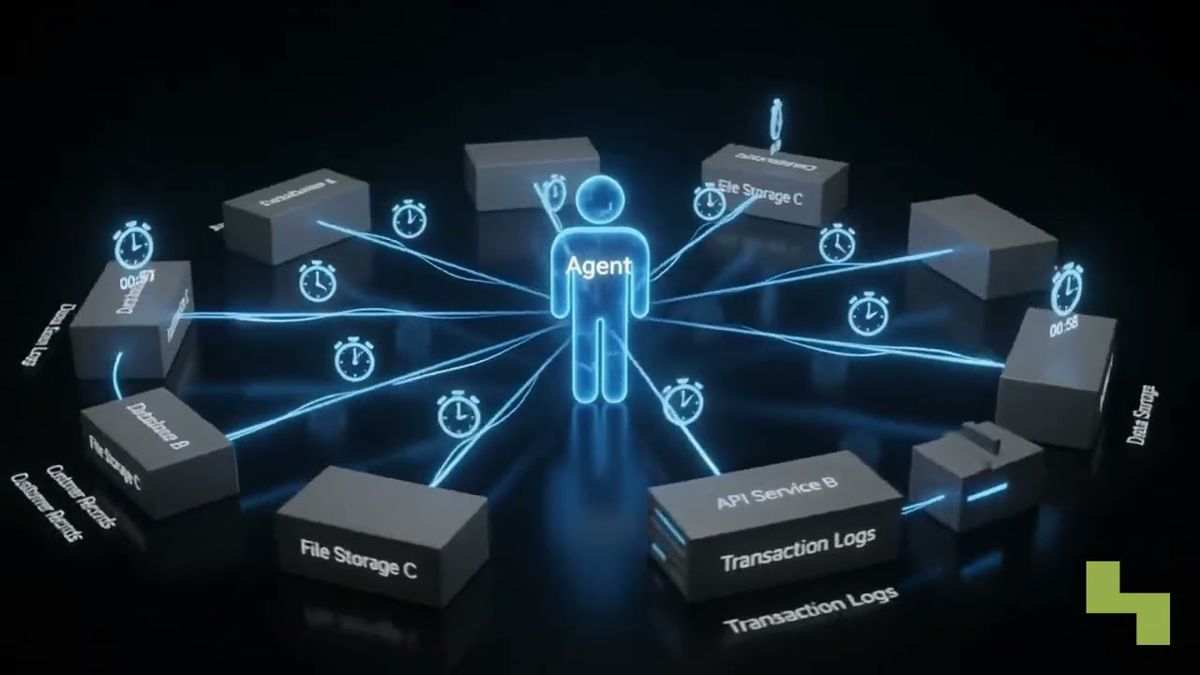
Conversations and agent workflows make it worse. A long answer raises the cost of the current call, then may come back as conversation history in later ones. Multi-agent systems compound it further when coordinators, specialist agents, evaluators and tool-handling steps each call a model.
Prompt and workflow design are therefore economic controls as much as quality controls. Cap response length. Ask for structured outputs. Skip history you don't need, retrieve only relevant context, and save the expensive models for the steps that need them.
Our goal, put simply: cut the tokens that don't improve the completed outcome. That's not quite the same as cutting tokens.

How Hyperlake helps
Hyperlake lets teams assemble and operate models, data services, applications, policies and monitoring in infrastructure they or their clients control. It gives direct visibility into infrastructure usage and cost, eligible inference endpoints can scale down when idle, and capacity can be right-sized for the workload. To assess the operating model for a specific deployment, talk to our team.
Frequently asked questions
How should a team calculate LLM cost per completed task?
Add the input and output token charges for every model call involved, then add allocated costs for retrieval, orchestration, compute, storage, monitoring, governance and maintenance. Divide by successful completed outcomes, not raw requests. That way you capture the retries, failed runs and multi-step workflows a simple per-call estimate misses.
Does using a smaller language model always reduce total cost?
No. A smaller model may cost less to serve or per token, but it can need more retries, more elaborate prompts, extra validation or escalation to another model. Compare on task success, latency, operational complexity and cost per accepted result. The cheapest single call isn't always the cheapest complete workflow.
When can self-hosting an LLM make economic sense?
When workloads are steady enough to use owned or rented capacity efficiently, or when control, privacy, deployment location and model choice justify the operational responsibility. Count GPUs, storage, serving software, engineering labor, upgrades and idle capacity in the math. The answer depends on each workload, not on some universal usage threshold.