Multimodal models are AI systems that take in more than one kind of input (text, images, audio, video) within a single architecture. Each input is converted into representations that share one reasoning context, so the model can notice how the inputs relate and answer from all the evidence together, which a text-only model has no way to do.
Look at what lands on your desk in a week: PDFs, diagrams, recorded calls, screenshots, maybe a camera feed. Very little of it is tidy text. That's reason enough for us to take multimodality seriously, since it's where your evidence already lives.
Which multimodal AI model capabilities are ready for production?
Advanced general-purpose models are now expected to handle text plus images, and audio understanding is widely available too. Video remains the hard one, since a single clip packs in many frames, sound, motion and timing.
What each modality asks of the model:
- Images: documents, diagrams, screenshots, photos and charts, limited by model quality and input resolution.
- Audio: speech, tone, timing, speaker changes and acoustic context, which is a lot more than a transcript.
- Video: linking events across frames and audio tracks, in the right order.
Our advice is simple: don't trust the demo, because a polished one says very little about production. Run your own documents, cameras, languages, environments and failure cases through it. Track latency, cost, evidence quality and how inputs get sampled. Then see what the model does when information is missing or ambiguous.
What is a multimodal model?
Any model that accepts two or more types of information and can reason across them. Text, images, audio and video are the usual set; some specialized systems also accept sensor readings or other structured signals.
Early language models had one channel: text in, text out. Anything else had to be converted first, with images going through optical character recognition or captioning and speech getting transcribed. Every conversion was a chance to lose something. The tone of a voice, the layout of a page, a detail in a photo, a sound in the background.
Multimodal AI models skip the conversion. All the inputs go into one shared context.
People often assume the output has to be multimodal too. It doesn't. A system can study an image, listen to a clip and still answer in plain text.
How do multimodal models process different input types?
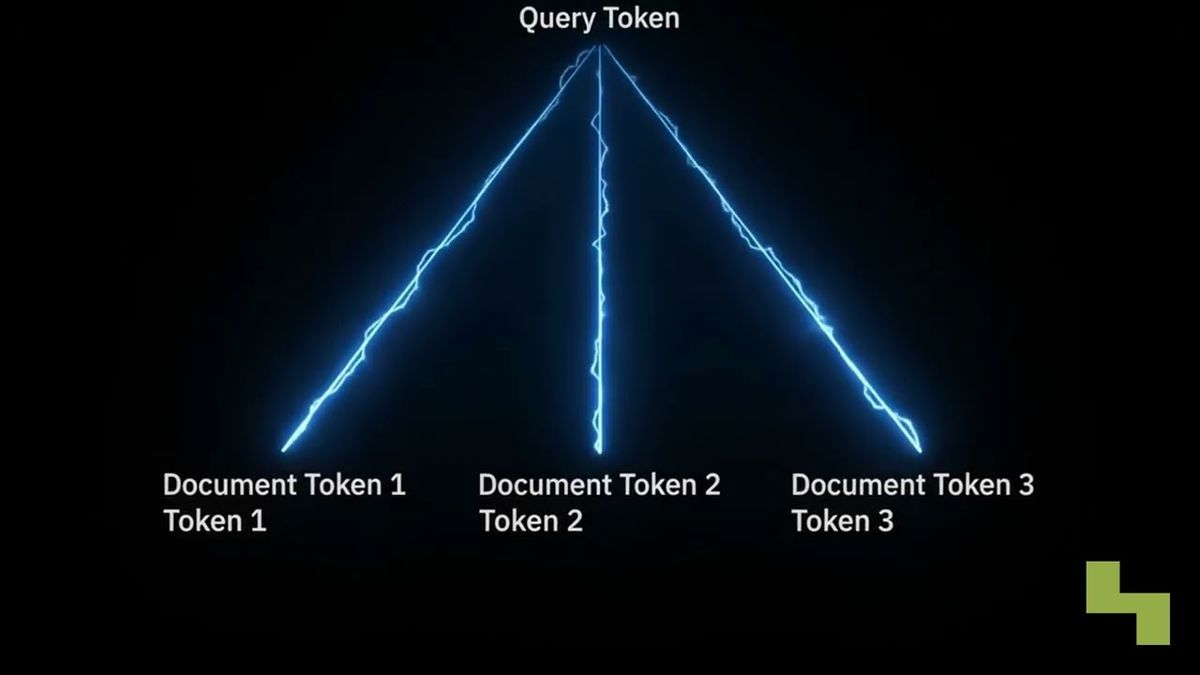
Every kind of input gets its own translator, called an encoder, which turns that input into numbers the model backbone can use. The resulting embeddings or tokens go into one shared context, where attention can connect evidence across modalities.
Here's the sequence. The model takes the inputs (text, images, audio, video, or a mix of whatever it supports). It encodes each input: an image turns into visual tokens, audio into a sequence of acoustic representations. Everything (visual, acoustic, text) then lands in a single context, and the model can look across all of it. Finally it responds, whether that means answering, classifying, summarizing or suggesting an action from the combined evidence.
Not every model is built this way. Some attach modality-specific encoders to a language model backbone, while others blend the modalities more deeply during training. Either way you end up in one place, with every input as a representation inside a single reasoning process.

How is cross-modal reasoning different from a model pipeline?
Imagine a quarterly report. The text says sales grew. The chart on page three slopes down.
Give both to a multimodal model and it reads the words and studies the chart in the same forward pass, which at least gives it a chance of catching the mismatch. It could just as well use a note scribbled on a diagram to decode an unclear sentence. Neither input holds the whole answer. Weighing how the modalities relate, jointly, is cross-modal reasoning, and it keeps alive evidence that a step-by-step pipeline would discard.
The pipeline version looks different. One model captions the chart, and a language model only ever sees the caption. Each stage is easier to test that way. But the caption becomes a choke point, and whatever the first model left out is gone for good.
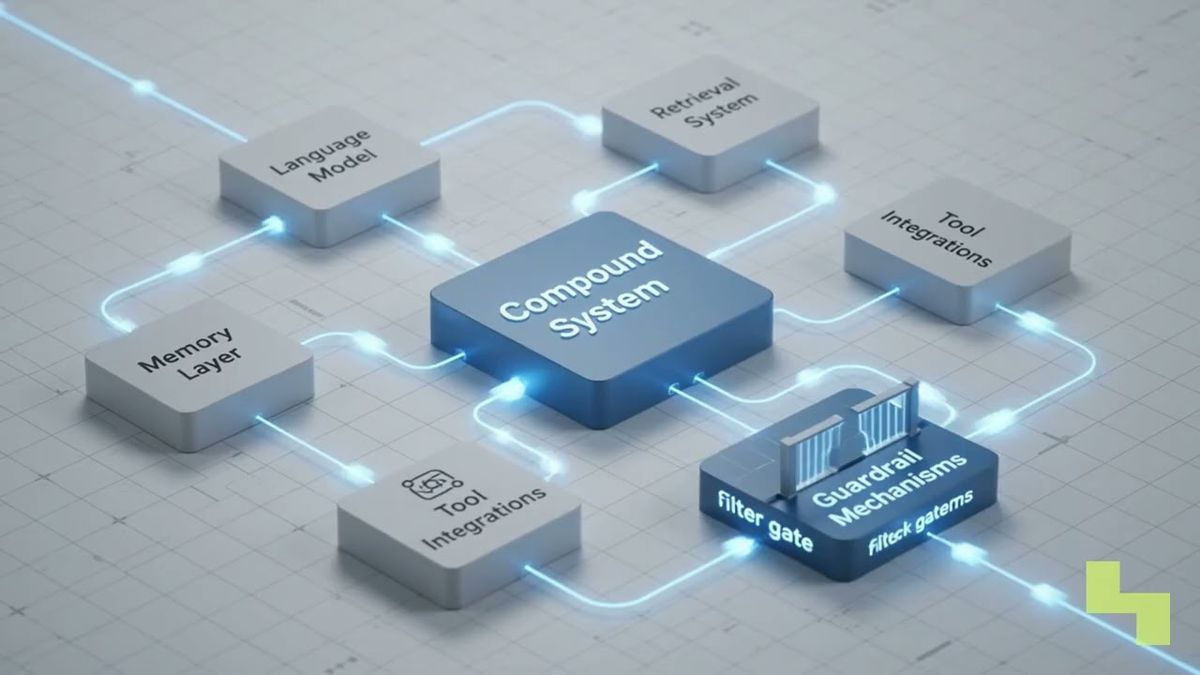
So it's either/or? No. Production designs often run shared multimodal reasoning next to specialist extractors, validators and policy controls, as part of a broader compound AI system.

How do multimodal models enable AI agents?
They give agents more to perceive. An agent can watch a screen, read a document, follow a camera feed or listen to audio, then pick an action based on what it noticed. Plain text can't describe those settings well enough.
Some generic examples of multimodal models inside agents: a document agent comparing the narrative with a chart before it flags an inconsistency; a robotics workflow reviewing recorded camera feeds alongside operational context; a support agent reading a user's screenshot next to their written description.
Sharper senses don't mean fewer controls. Agents still need authenticated access, scoped tools, approved data, audit trails and human review before actions that matter, and disciplined agent grounding keeps their conclusions tied to the evidence in front of them.
Going from "text in" to "world in" is a big change. Add the progress in reasoning models, and multimodality looks like a serious architectural direction for AI systems that perceive what's happening and act within set limits.
How Hyperlake helps
Hyperlake is the AI cloud for your team and your agents, on your cloud. Teams use it to assemble, deploy and govern the data, models, applications and tools behind Physical AI, enterprise agents and AI-native products, in infrastructure they or their clients control. The modular platform can cover the surrounding data, model-serving, identity, policy, observability and lifecycle needs, with engines and validated integrations picked for each deployment. To talk through a multimodal or agentic workload, talk to our team.
Frequently asked questions
Does a multimodal model have to generate images or audio?
No. "Multimodal" describes what a model can take in, not every format it can put out. Plenty of models accept text, images and audio and reply only in text. Producing media takes suitable output models or decoders, and the app needs safety and governance controls around them.
Is audio understanding the same as speech transcription?
No. Transcription turns spoken words into text; audio understanding can also pick up tone, timing, speaker changes and background sound. A transcript can feed a system, but it leaves out part of what was in the recording.
Why is reliable video understanding harder than image analysis?
A video is many images in sequence, often with speech, ambient sound and motion layered on top. The model has to find the frames that matter and link events without scrambling their order. Production adds bigger inputs, latency and sampling choices, which is why you test for events the model missed or put in the wrong order.
When should a team use separate specialist models?
When the task calls for a specialized detector, stages you can test one at a time, or a controlled intermediate format. Pipelines can also make debugging and policy enforcement simpler. Many production architectures mix both: specialist components handle defined tasks, and a multimodal model reasons over their outputs plus the original context.