Nobody should need to know your storage layout to write a fast query. Iceberg table partitioning uses transforms defined in metadata to organize data, so users never see derived partition columns. A compatible query engine turns a filter on a logical column into a partition filter, skips the irrelevant files, and copes with several partition layouts as the table evolves. Query design and physical organization stay apart.
Partitioning is one of those data lake decisions that hurts most when it's wrong. A poor grouping can turn a selective query into a broad file scan. With hidden partitioning, good pruning no longer depends on every query writer understanding how the files are stored.
What is Iceberg table partitioning?
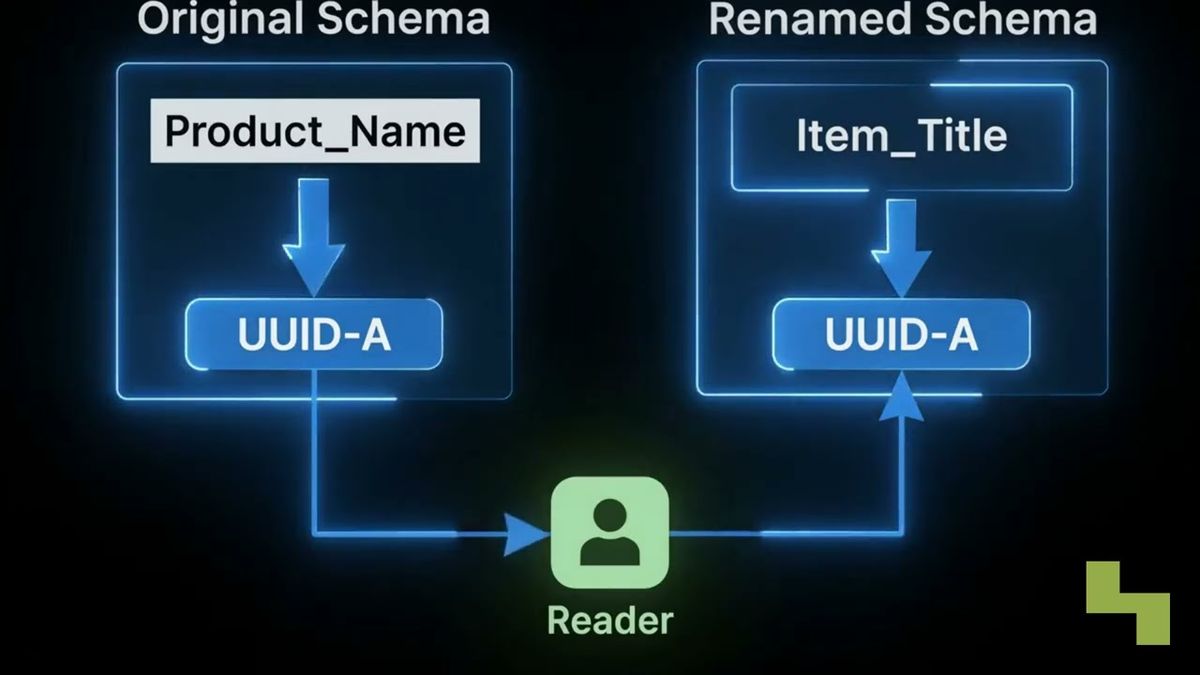
Files get grouped by transforms defined in table metadata. Users keep querying the table's logical columns. They don't filter by hand on extra columns that exist only for physical organization.
A partition specification can apply year, month, day or hour transforms to timestamps. Identity, truncation and bucket transforms are there too, where they fit the data and the access pattern. A table can partition events by day from an event_time column without adding a separate event_day column to the visible schema.
Keep two ideas apart. The schema describes the records users work with. The partition specification describes how files are organized for pruning.
Iceberg stores partition information in metadata and doesn't rely on partition values encoded in directory paths. That metadata-first design belongs to the wider data lakehouse architecture, which separates storage, table management and query execution.
How does Iceberg hidden partitioning improve query performance?
The engine does the translation, so people don't have to. A compatible engine can derive partition filters from ordinary query predicates. Filter event_time to a date range and the engine pushes that predicate through the table's day transform, then drops unrelated partitions and files.
Pruning generally runs like this:
- The query filters a logical source column, such as a timestamp.
- The engine reads the active Iceberg partition specifications.
- It derives the relevant partition values and evaluates Iceberg metadata.
- It reads only the files that might hold matching records.
The engine may never open piles of irrelevant files. And users don't need to remember a separate physical partition column or repeat the exact transform in every query.
Pruning can't rescue a bad layout, though. A poor transform, an overly broad filter, skewed data or lots of small files can still pile on work. File sizing, compaction, sorting, metadata maintenance and the engine's Iceberg support all count next to the partition specification. Iceberg partitioning best practices begin there.

How is Iceberg different from Hive-style partitioning?
Traditional Hive-style partitioning puts the physical layout in front of users. Partition values show up as columns and are commonly encoded in directory paths. Iceberg defines the transforms in metadata and lets supported engines apply them, so nobody queries the physical layout directly.
Take a Hive-style monthly layout. The table might carry a month column, and you'd need an explicit filter on it for reliable pruning. Filter only on the original timestamp and you could miss the optimization, depending on the engine and the query. Anyone who has debugged a slow Hive query has probably hit this.
Iceberg table partitioning can keep a clean timestamp schema and define a month or day transform behind it. Query writers get a stable logical interface, and table administrators get more control over physical design. Application SQL is less tied to storage conventions, as long as the engine supports Iceberg's partition and metadata semantics correctly.
It's one of several architectural differences covered in Apache Iceberg vs. Delta Lake, including how table formats manage metadata, transactions and file-level state.

How does Iceberg partition evolution work?
You can change your mind without rewriting the table.
Administrators change the partition specification, and existing data files aren't rewritten right away. New writes follow the new specification. Older files stay tied to the one they were written under.
Picture a table partitioned by month. It grows, or its queries get more selective, until daily partitioning makes more sense. An administrator changes the specification so later files use a day transform. Iceberg metadata records which specification applies to each file, so the planner can prune across monthly and daily layouts in the same table.
That works because partition values and specifications live in table metadata, not just in fixed directory structures. Iceberg's metadata model, including the historical state described in Iceberg snapshots, gives engines what they need to read each file correctly.
Plan for one thing. Changing the specification doesn't reorganize old files after the fact. Existing monthly files keep their original pruning granularity until an optional rewrite reorganizes them. Our advice: treat partition evolution as a safe, forward-looking change, and decide separately whether rewriting older data is worth the compute and operational cost.
How Hyperlake helps
Hyperlake can run an Iceberg and object-storage data foundation with a fitting query engine, such as Trino, inside infrastructure the customer controls. Teams can combine that foundation with governed identity-to-data access, policies, audit, lineage and lifecycle operations, with procedures that depend on the engine and deployment. To discuss an Iceberg environment for enterprise data or AI workloads, talk to our team.
Frequently asked questions
Does hidden partitioning mean an Iceberg table has no partitions?
No, it still has partitions. Hidden partitioning only means the physical partition transform doesn't appear as a separate column users must reference. The table organizes files with a partition specification, and compatible engines read it from metadata and derive partition filters from predicates on the logical source columns.
Will changing from monthly to daily partitions reorganize old data?
No. Updating an Iceberg partition specification affects files written after the change, and existing files keep their monthly organization. The planner can evaluate both layouts because Iceberg records the applicable specification in metadata. Moving historical files into daily partitions takes a separate rewrite, if finer pruning is worth the cost.
Do applications need to know an Iceberg table's partition spec?
Generally not. Applications query logical columns, and a compatible Iceberg engine projects supported filters through the partition transforms automatically, so there are no hidden derived values to build predicates against. Platform teams still need to understand the spec, to judge performance, maintain files and evolve the layout as access patterns change.
What partition transform should an Iceberg table use?
It depends on data volume, value distribution, write frequency and the filters people really use. Time-based event data may suit year, month, day or hour transforms. Other columns may suit identity, truncation or bucketing. Pick enough granularity to prune a useful amount of data without fragmenting the file layout for no reason.