Language model failures are sneaky, and too often the first sign is a user complaint. LLM evals are systematic, repeatable measurements of how a model behaves across defined inputs. They catch quality regressions before release, let you compare prompts or model versions, and watch for drift in production. Where conventional tests pass or fail, LLM evaluations usually score correctness, relevance, safety, style or task completion against explicit criteria.
The failures are subtle, and they vary from run to run. A reliable evaluation practice gives engineers real evidence when they ask whether a model, prompt, retrieval or LLM fine-tuning change is safe to ship.
What are LLM evals?
Structured tests that measure how a model, or a compound AI system, behaves on representative tasks. Each defines the inputs, the expected behavior, the scoring criteria and the thresholds a change must clear before it moves on.
Why not just write ordinary code tests? Because those usually check deterministic outcomes: the function returns the expected value or throws a clear error. Model outputs are probabilistic. They can sound plausible while being inaccurate, unhelpful, ungrounded or out of policy. Even with settings that reduce randomness, prompt changes, model updates, retrieved context and tool behavior can all shift results.
So test what users actually care about. Does it answer from approved evidence? Follow the formatting rules? Pick the right tool, refuse unsafe requests, finish a domain-specific workflow? Framed that way, a vague feeling about "quality" turns into repeatable engineering evidence.
Which LLM evaluation methods should teams use?
A mix of four. No single scorer works for every task, and the right blend depends on whether a ground truth exists, how nuanced the output is, and how often the test has to run.
Reference-based evals compare an output with a known correct answer. They're fast and precise for classification, extraction, structured generation and questions with verifiable answers, but they can't fully judge open-ended responses.
Reference-free evals score properties like relevance, clarity, groundedness or policy adherence, so no single correct answer is needed. They suit open-ended generation, as long as the rubric is specific.
Human evals put domain experts directly on the outputs. Still essential for nuance, trust calibration and ambiguous cases; time and cost make them hard to run all the time.
LLM-as-a-judge uses a capable model plus a defined rubric to score another model's output. It's fairly fast and fits automated regression testing, pull-request checks included. Calibrate it against human judgments and watch for evaluator bias.
All of these test system behavior, not just the underlying model. That's the point for compound AI systems, where retrieval, prompts, tools, data and orchestration all shape the result.

How do offline and online LLM evals differ?
One runs before you ship, the other after. Offline evals use a fixed dataset before deployment; online evals assess sampled production interactions once you're live. They catch different kinds of failure, so you want both.
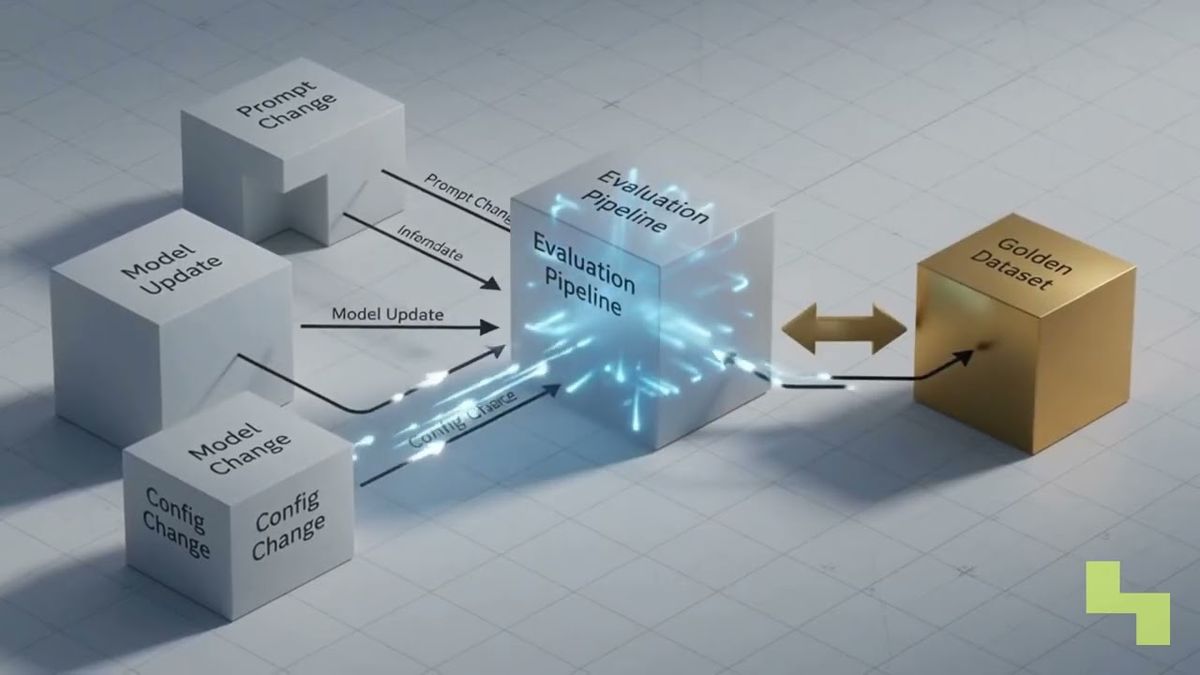
Offline evaluation is for the regressions you introduce on purpose: prompt edits, fine-tuning, model swaps, retrieval changes, application updates. Inputs are fixed, which means you can compare candidates under identical conditions before anyone signs off on a release.
Online evaluation is for drift and surprises in real usage. New query patterns. Changing data. Broken integrations. Cases the offline benchmark never covered.
Handle production samples under proper privacy, retention, access and review policies, and be extra careful in a private AI or private LLM deployment.

What is a golden dataset for LLM evaluation?
Think of it as the benchmark you trust: a curated set of representative inputs, expected outputs or scoring criteria, and known failure cases. It's the stable base for regression testing across model, prompt and system changes.
Build it around the user journeys that matter and the failures that cost the most. Convenient examples are tempting, and we'd resist them. A useful record can hold the input, relevant context, expected behavior, unacceptable behavior, the rubric, and metadata for slicing results by task or risk.
Why bother? A prompt change might fix one formatting issue and quietly break many older cases. Run the candidate against the golden dataset and you see that tradeoff before release.
Add validated production failures over time, and version the dataset so comparisons stay meaningful.
How do LLM evals support AI audit readiness?
They document what the system was tested against, how outputs were scored, who approved changes and how production behavior is monitored. That evidence feeds risk management, technical documentation, traceability and internal assurance.
Check the current application timeline for the exact system and organizational role. The European Commission currently lists 2 December 2027 for Annex III high-risk use cases and 2 August 2028 for high-risk systems embedded in regulated products under Annex I; other AI Act requirements have different application dates. Covered organizations may need evidence about testing, accuracy, robustness, risk controls, logging and post-market monitoring, and evaluation records can contribute. An eval suite alone does not establish compliance.
Tie evaluation results to model and prompt versions, datasets, rubrics, approvals, incidents and remediation actions. A broader AI audit checklist helps place model testing inside the full governance process.
How Hyperlake helps
Hyperlake supports private AI environments that can include open-model serving through KServe, fine-tuning and evaluation, subject to the selected deployment and validated integrations. Teams can assemble models, data services, applications, policies, observability and lifecycle controls in infrastructure they or their clients control. To discuss an evaluation environment for your workloads, talk to our team.
Frequently asked questions
Can an LLM judge replace human evaluators?
It can take over frequent regression checks, but we wouldn't let it replace human review completely. Experts still need to define rubrics, judge nuanced domain behavior, dig into disagreements and calibrate automated scores. Compare against human ratings every so often and you'll expose systematic judge bias, or criteria the evaluator model reads badly.
How often should a golden dataset be updated?
Whenever you find a validated failure mode, add a major use case, or change what the system is expected to do. Keep old versions rather than silently replacing cases. Versioning lets you tell genuine model improvement from a benchmark change, and it keeps historical release comparisons readable.
What should an LLM regression test measure?
Behavior tied to the application's purpose and risks. Depending on the task, that could be factual correctness, groundedness, relevance, tool selection, structured-output validity, policy adherence, refusal behavior, latency or task completion. Give every metric an explicit rubric and a release threshold that engineering and domain stakeholders both understand.
Do deterministic model settings eliminate the need for evals?
Unfortunately not. Deterministic settings make repeated runs more consistent, but consistency doesn't prove an answer is correct, safe, grounded or useful. Prompt, model, retrieved data, tool, policy and application-code changes can still cause regressions, so you still need repeatable evaluation across the whole system.