Row filtering and column masking for data security are query-time controls that govern access inside a table. Row filters limit which records a person or workload can retrieve; column masks transform sensitive values based on identity or attributes. Together they protect data more finely than table-level permissions can, and the stored data never changes.
We'd worry less about someone breaking in and more about the query that forgot a filter.
People, applications and AI agents all want different views of the same dataset. These controls mean you don't have to depend on separate tables, app-specific filters, or users remembering to constrain every query.
How do you enforce row- and column-level security in an AI application?
Hypothetical: a regional employee asks an AI agent for "all our customers." The agent runtime can reach the whole customer table. Should the answer cover the whole table? No.
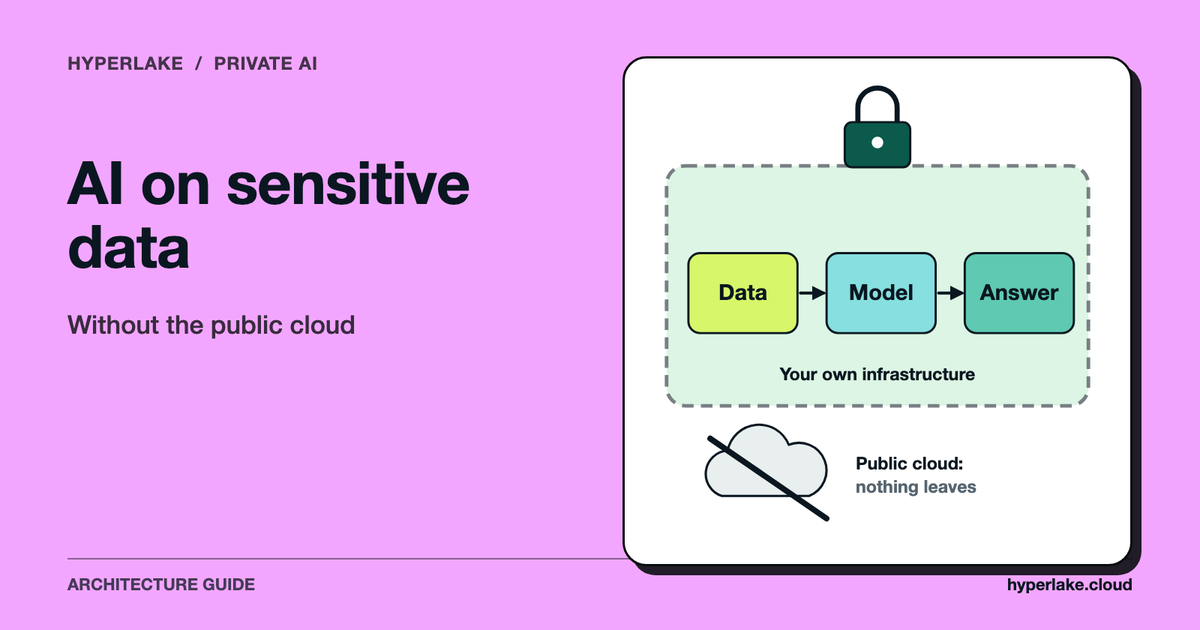
So give the agent the permissions of the person or workload it represents, never the broad permissions of a shared agent service account. The same row filters and column masks should apply whether access comes from a person, an application, an agent or a direct query tool. Connectivity shouldn't turn into authorization, and an agent that has system-level reach to several datasets while acting for users with very different permissions is exactly where that goes wrong.
What does it take? An identity-aware request path. The system authenticates the requester, carries scoped user or workload identity into the data request, evaluates policy, and enforces the resulting filters and masks where the query reaches the data.
Enforcement should also produce logs that link the request, the represented identity, the policy decision and the resource accessed. Those records help you investigate odd results and show that an agent didn't go around the reporting or application layer. For consequential operations, pair data access controls with tool permissions and human approval requirements.

How does dynamic data masking protect sensitive values?
By changing selected values before results reach a requester who lacks full clearance. Someone authorized gets the original; everyone else gets a redacted, partial, tokenized or otherwise masked version.
An account number might show in full to an approved finance workflow and only as its last characters to a support user. The stored value stays the same. Only what the query returns changes, according to policy.
Masking isn't the same as dropping a column, since it can keep enough structure for an authorized task without revealing the whole value. And it isn't encryption at rest, which protects stored media but doesn't decide what an authenticated query may reveal after decryption.
Where you enforce it matters. Mask at shared data access points, not just in a reporting interface; otherwise a user can skip the presentation layer and pull the raw field through another tool.
All of this belongs inside a broader AI data governance program covering classification, identity, policy, audit and approved uses.
How does row-level filtering work?
The user writes an ordinary query, and the system quietly adds the condition they're allowed to see. Row-level filtering attaches a policy predicate based on the requester's identity, role, region, tenant or other approved attributes, so only authorized records come back.
A sales rep queries a shared customer table with no territory condition at all. The data access layer evaluates the rep's identity and applies the assigned-territory restriction automatically. The rep never sees the filter, yet it's part of the enforced query path every time.
Compare that with trusting every report, application or agent to include the right WHERE clause. A centrally enforced policy keeps direct SQL, business intelligence tools and application requests consistent, as long as they go through the same governed access point.
Keep row policies explicit, testable and tied to identity attributes you can trust. Decide what happens when attributes are missing or conflict. The usual answer is deny, and widening access by accident is the thing to avoid.
This is close kin to attribute-based access control for data, where decisions use contextual attributes and not roles alone.
Row filtering vs column masking: what's the difference?
One decides which rows you get. The other decides what the values in those rows look like. Both work inside a table, and both adapt the result to whoever is asking.
Traditional table-level access is binary: you can query the table or you can't. That's fine when everyone allowed in may see everything, and it falls apart for the ordinary distinctions inside customer, financial, operational or workforce data.
Take a customer table. A global administrator sees every customer record. A regional employee sees only customers assigned to that region, and a support user sees the relevant records with account numbers masked. A highly authorized user gets the original sensitive values.
Row filters and column masks build all of those views at query time, with no duplicate copy of the data for each audience. The two controls complement each other.

How Hyperlake helps
Hyperlake supports governed access through OAuth/OIDC sign-in, validated JWT identity, OPA policy decisions, and enforcement and logging at integrated access points. Teams can assemble data services, models, applications, policies, secrets and monitoring in infrastructure they or their clients control; specific behavior depends on the chosen engines and deployment. To discuss an identity-to-data architecture for users and agents, talk to our team.
Frequently asked questions
Can row filtering replace separate tables for each region or tenant?
Often, yes. Row filtering reduces the need to copy a shared table just to give different groups different record views, since a policy can restrict results by region, tenant, business unit or another trusted attribute. Separate storage may still be the right call when legal, residency, operational or isolation requirements demand a stronger boundary than query-time filtering.
Is column masking the same as encrypting a sensitive column?
No. Encryption makes data unreadable without the required key, whether stored or in transit depending on the method. Dynamic masking assumes the query system can process the value, then changes what it returns based on the requester's authorization. Many systems use both together.
Do filters and masks still apply when someone uses direct SQL?
They do, if policy enforcement sits on the shared query or data access layer that direct SQL and other clients use. If the controls live only inside a dashboard or application, another access path can bypass them. Find every route to the data and make sure each one hits an equivalent enforcement point.
Should an AI agent connect with a shared database account?
We'd avoid it. A shared account makes it hard to apply each user's permissions and attribute-based policies accurately. A better design carries scoped user or workload identity into the request, so the data layer can apply the right row filters and column masks. Then the agent's ability to reach a dataset never grants every represented user access to all of it.