Choose between SGLang and TensorRT-LLM using the model, hardware, workload and software version you will actually deploy. Both provide optimized LLM serving. Current TensorRT-LLM uses a PyTorch-native execution backend; older engine-building descriptions do not describe its current deployment path. Compare request shape, prefix reuse, concurrency, deployment effort and service-level latency before choosing.
The engine shapes request throughput, token latency, memory use, scaling behavior and operational complexity. It's one of the bigger LLM inference decisions you'll make.
SGLang vs TensorRT-LLM: how do they differ?
Both frameworks optimize LLM inference and support dynamic production workloads. Compare their current model support, scheduling, caching, quantization, hardware requirements and operating interfaces rather than treating one as flexible and the other as necessarily compiled.
SGLang offers runtime primitives for model-serving programs, including structured generation and multi-step workflows. Its prefix-aware approach can reuse cached prompt computations when requests share context. Dynamic scheduling helps it cope with shifting request shapes and branching execution paths.
NVIDIA's current documentation describes TensorRT-LLM as PyTorch-native. Its migration guide states that the TensorRT engine backend was removed: supported Hugging Face checkpoints load directly, without the former trtllm-build engine-build step. Version-specific optimized kernels, parallelism and memory management still matter, so check the release and model you intend to run.
"Flexibility versus speed" is a tempting summary. We'd resist it. For either engine, results depend on the model, quantization, hardware, request distribution, sequence lengths, batching policy and configuration. Treat the architecture as a starting hypothesis and validate it against your own production workload.

What workloads are a good fit for SGLang?
Messy ones.
SGLang suits shared prompt prefixes, structured outputs, multi-turn interactions and unpredictable execution paths. You tend to see those in agent systems, tool-using applications and pipelines that generate constrained text.
SGLang's runtime supports workloads with varying request shapes and shared prefixes. Evaluate the supported scheduling and structured-generation behavior for your traffic; application-level branching and tool execution still need orchestration around the serving engine. Those requirements should not be confused with an obligatory separate compiled graph for every workflow in another runtime.
Prefix reuse pays off when many requests share a system prompt, a policy, a document prefix or a conversation history. Reusing the relevant cached computation can cut repeated work, though how much depends on real prefix overlap, cache capacity and traffic patterns.
SGLang looks attractive, then, when deployment velocity and application flexibility matter next to serving performance. Still test memory pressure, tail latency, failure behavior and scheduling under realistic concurrency.
When should teams consider TensorRT-LLM?
Consider TensorRT-LLM when its current supported models, NVIDIA hardware requirements and production interfaces fit the workload. Evaluate GPU efficiency, concurrency and latency on the actual release rather than assuming an engine-compilation workflow is required.
Optimized kernels, batching, parallelism and memory management can affect throughput and latency. Tensor parallelism can distribute a supported model across GPUs; the right configuration depends on model size, hardware connectivity, memory and the target service objective.
Record the operational requirements of the release you will deploy: model loading, checkpoint formats, quantization support, hardware, observability, upgrades and rollback. Current TensorRT-LLM's PyTorch backend loads supported Hugging Face checkpoints directly; do not include the removed TensorRT engine-build process in a new deployment plan unless you are intentionally assessing a legacy release.
Evaluate TensorRT-LLM against the current release, supported model and accelerator, measured serving results and operating requirements. Include deployment and maintenance effort without assuming that the removed TensorRT engine-build workflow is required.
How should inference engines be benchmarked?
With your models, your hardware, your traffic shapes and your service objectives. Generic tokens-per-second numbers can't capture branching behavior, prompt reuse, deployment effort or the latency users actually feel.
A useful evaluation covers:
- Latency: time to first token, inter-token latency, end-to-end latency, tail behavior.
- Throughput: completed requests and generated tokens under realistic concurrency, prompt lengths and output lengths.
- Memory: model weights, KV cache growth, prefix-cache behavior, headroom during traffic spikes.
- Scaling: tensor-parallel configurations, replica behavior, routing, recovery when an instance fails.
- Operations: build time, deployment velocity, configuration complexity, observability, upgrades, rollback procedures.
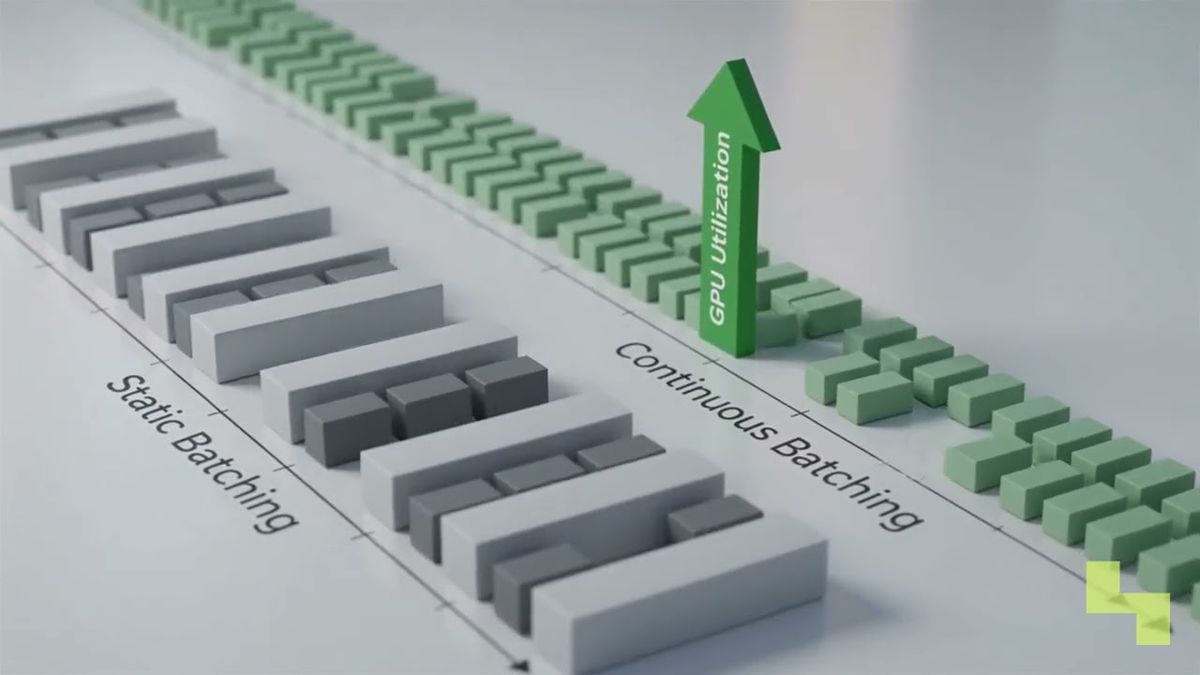
Keep engine performance and model quality apart. Quantization or model conversion can improve resource use and change output behavior at the same time. So run performance tests alongside enterprise LLM testing and benchmarking. For high-concurrency services, knowing how continuous batching works also explains why results shift with request volume and sequence length.
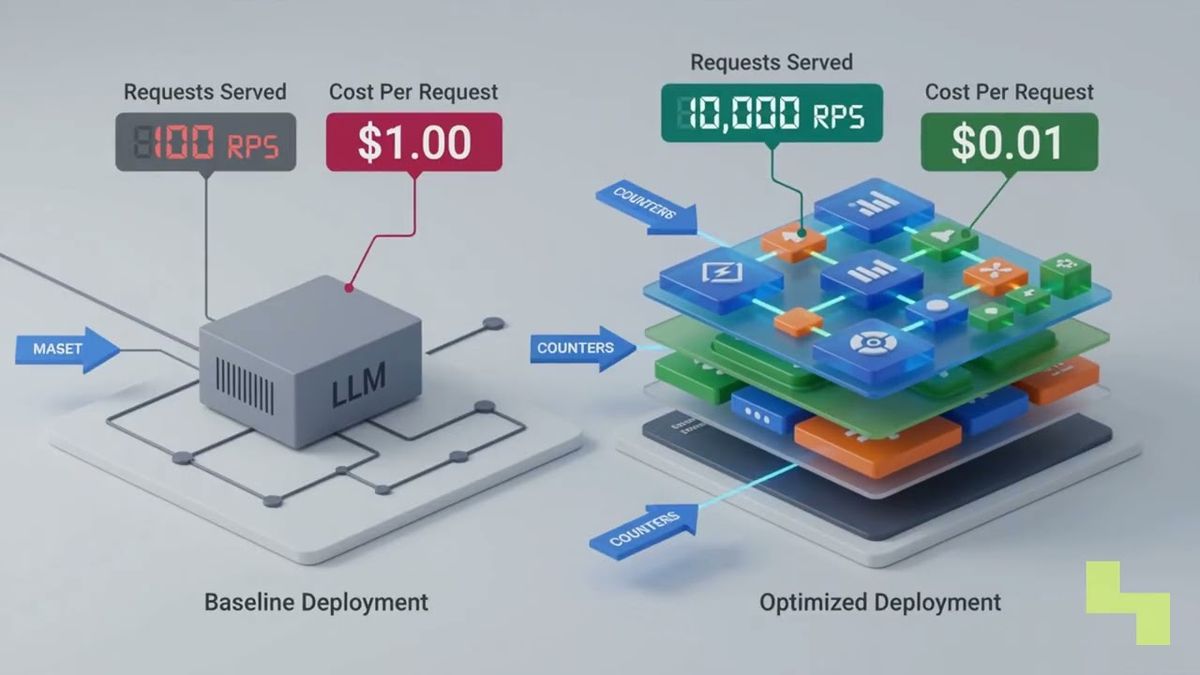
Base the final choice on measured service-level results and operational fit. Test shared-prefix traffic, structured outputs, representative prompt and output lengths, concurrency and failure recovery on the same hardware and model where supported. Any operating-cost advantage must follow from that workload's measured capacity and complete running costs.

How Hyperlake helps
Hyperlake lets teams assemble, deploy, govern, observe and maintain private model services alongside the data, applications, policies and infrastructure they need. It can serve open models through KServe on selected compute, with the specific engines, lifecycle procedures and automations depending on the deployment. To discuss a model-serving environment in your infrastructure or a client's, talk to our team.
Frequently asked questions
Is SGLang always better for AI agent workloads?
Not automatically. SGLang's dynamic scheduling, structured generation and prefix-aware execution can suit agent workflows with branching paths and shared context, but results depend on the application. Test your actual tool-call patterns, prompt overlap, sequence lengths, concurrency and latency requirements. Don't choose from the workload label.
Does TensorRT-LLM always deliver higher throughput?
No engine wins on throughput across every model and traffic pattern. Evaluate the current TensorRT-LLM release on supported NVIDIA hardware, with the actual batching, model, quantization, parallelism, memory and request settings. Its current PyTorch-native deployment path differs from the legacy compiled TensorRT-engine workflow.
Can an organization operate both inference engines?
Yes, if the platform can operate both serving paths with suitable packaging, routing, observability, upgrades and resource allocation. Assign workloads using measured compatibility and service-level results; include the cost of maintaining two stacks instead of assuming a fixed agent-versus-stable-workload split.
Which metrics matter most when comparing inference engines?
Start with time to first token, inter-token latency, end-to-end and tail latency, request throughput, token throughput, GPU memory use and utilization, all under realistic concurrency. Then look at deployment time, scaling behavior, failure recovery and upgrade complexity. If model conversion or quantization differs between the engines, check output quality too.