LLM cost attribution assigns model usage and spend to the team, product, feature, model version or customer that caused it. You attach governed metadata to each request, keep that context in a cost record, and add the records up along whichever financial dimensions your organization uses for accountability. That's AI cost attribution in one breath.
A provider invoice can show total consumption and still say nothing about which workload produced it. Good attribution takes one undifferentiated AI bill and turns it into something engineering, product and finance can each act on.
What is LLM cost attribution?
It's the link between a model request, the cost it produced and the business or technical owner who answers for it. You work from request-level evidence, and you stop carving up a total invoice by guesswork.
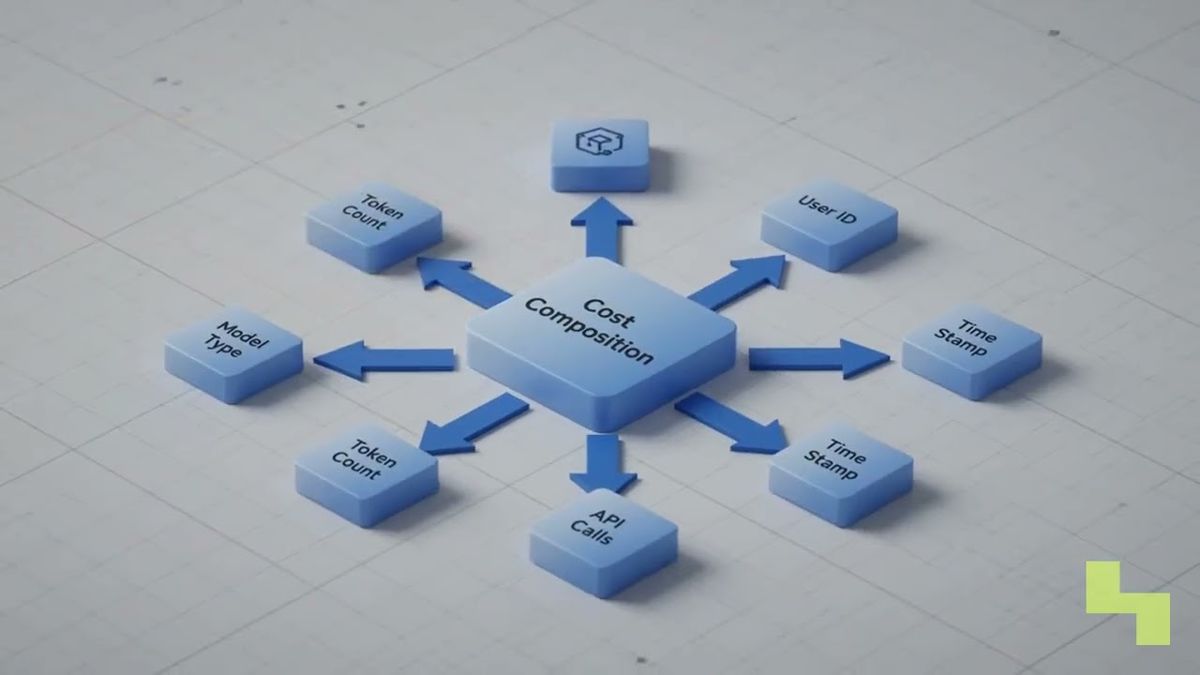
A useful cost record begins with metadata captured when the request is made. Usually that means:
- The team or cost center responsible for the request.
- The feature, application or product area generating it.
- The model and model version that handled it.
- In a multi-tenant application, the customer or organization that triggered it.
The record also carries the usage details needed to calculate or reconcile cost: request identifier, timestamp, metered model consumption. Once those are in, teams can aggregate records along whatever dimensions financial governance uses.
Keep one distinction straight. Attribution uses evidence attached to individual requests. Allocation divides a shared bill by a defined rule. You may need allocation when historical metadata doesn't exist, but the result is an estimate, and it's no substitute for direct accountability.
Why do shared API keys prevent accurate cost attribution?
A shared API key says which account or credential is using a provider service. It doesn't necessarily say which product, team, feature or customer sat behind each request, so the invoice reports aggregate usage against the key, and that's the end of it.
Imagine 20 applications on the same credential. Provider billing can show their combined token consumption without revealing which application caused a particular jump. Finance watches spending climb. Engineering can't reliably pin the change on a release, a customer segment or a workload.
Teams sometimes split the invoice using traffic estimates, user counts or fixed percentages. That's fine for rough budgeting. The trouble is that it drops the causal link between a request and its owner, which makes legitimate growth hard to tell apart from inefficient prompts, retries, unexpected usage or a feature-level anomaly.
So AI cost observability has to reach below the provider invoice. The aggregate amount charged isn't enough; the system needs request-level context too.
Where should LLM cost attribution be enforced?
At the most consistent control point your model requests pass through. We think a central AI gateway is usually far easier to govern than separate instrumentation that each application team maintains on its own.
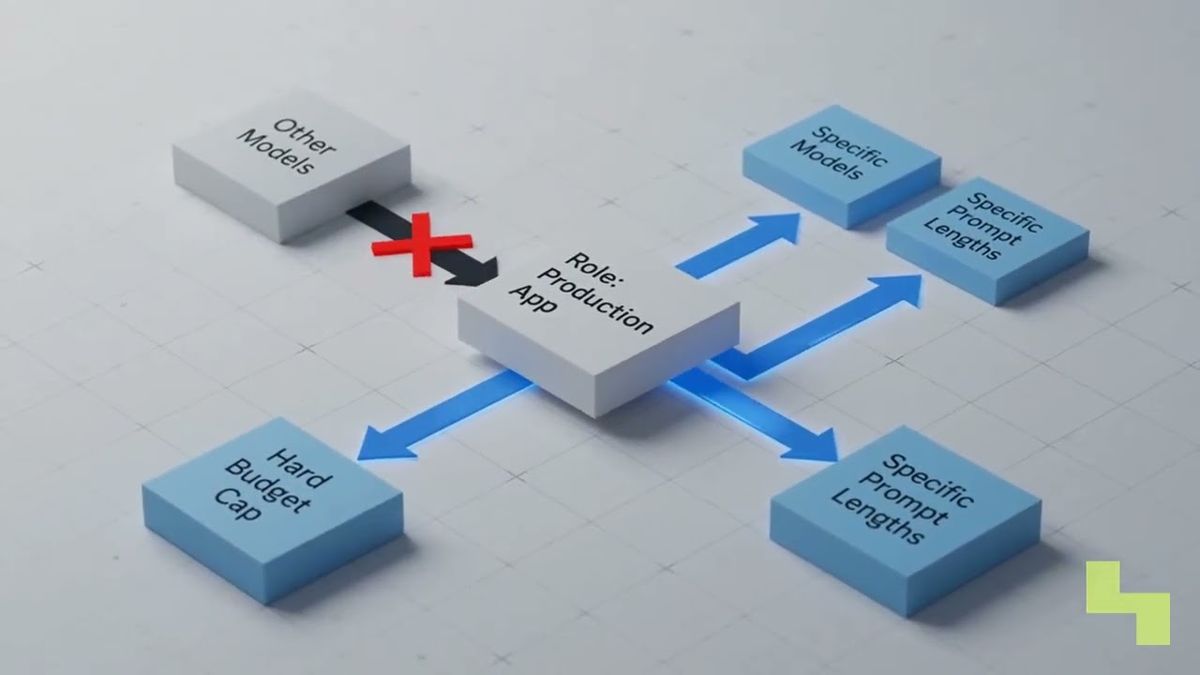
Under gateway enforcement, every request must carry approved team, feature, model and tenant tags before the gateway routes it. The gateway validates required fields, rejects or quarantines incomplete records, and writes usage against those dimensions as requests happen. Naming rules and reporting conventions also have one place to evolve.
When applications call model providers directly, each one needs SDK-level instrumentation. That can still produce useful records. Consistency is the risk: teams use different field names, forget tags, or calculate cost differently.
In practice, four steps:
- Define the financial dimensions and controlled values the organization needs.
- Attach and validate those values at request time.
- Store usage and cost records together with the original attribution context.
- Reconcile aggregated records against provider invoices and internal reports.
Lock down who can assign or change cost-center and tenant tags as well. If you don't, attribution metadata can end up incomplete or misleading even when every request technically includes it.

What can teams do with attributed LLM costs?
A lot, as long as enough context survives to tie spending to the group or activity behind it.
- Showback or chargeback: reports show consumption to the responsible team, or assign that spending to its cost center.
- Targeted anomaly detection. Alerts name the team, feature, model or customer driving an increase, so you don't wait for total spending to cross a broad threshold.
- ROI analysis, where product leaders set feature costs beside relevant business measures and decide which AI investments should continue, change or stop.
Attribution doesn't answer every financial question alone. You still need policies for shared platform costs, discounts, reserved capacity and infrastructure that several workloads use. A wider FinOps approach for AI sets out how those costs get allocated, reviewed and acted on.
How Hyperlake helps
Hyperlake lets teams deploy and govern models, applications, data services, policies and monitoring in infrastructure they or their clients control. Its operating approach gives direct visibility into infrastructure usage and cost, and shared controls help teams manage identity, access, observability and lifecycle operations around AI workloads. Per-request LLM attribution still needs a suitable metadata and cost-record design for the deployed applications and model services. To talk through the right operating model for your environment, talk to our team.
Frequently asked questions
How do you attribute LLM costs back to individual teams or projects?
Tag every request with the responsible team or cost center, the feature or project, the model and, where relevant, the tenant. Store those tags in the cost record. Enforcing them at a central gateway keeps them consistent, and reports can then roll spending up by team or project without losing where it came from.
Can a model provider invoice identify which feature generated the cost?
Generally not. An invoice ties consumption to an account, project or API credential. It won't reliably name an internal feature, team or customer unless that context is captured and kept separately. Where several applications share one credential, the invoice alone can't give you request-level attribution.
What metadata should every LLM request include for cost reporting?
The most useful fields: the responsible team or cost center, the product or feature, the model and model version, and the customer or tenant where applicable. Keep them in the cost record next to a request identifier, a timestamp and measured usage, so reports can aggregate spending with the original context intact.
Should internal LLM chargeback exactly match provider pricing?
It doesn't have to. Organizations may use provider rates, internal transfer prices, or allocation rules that fold in shared infrastructure and platform costs. Pick a method, document it, apply it consistently and make it reconcilable with actual invoices. Then teams understand both their measured consumption and the financial policy applied to it.